When an AI Cannot Tell a Leak from a Hallucination: A Multi-Model Guardrail Case Study
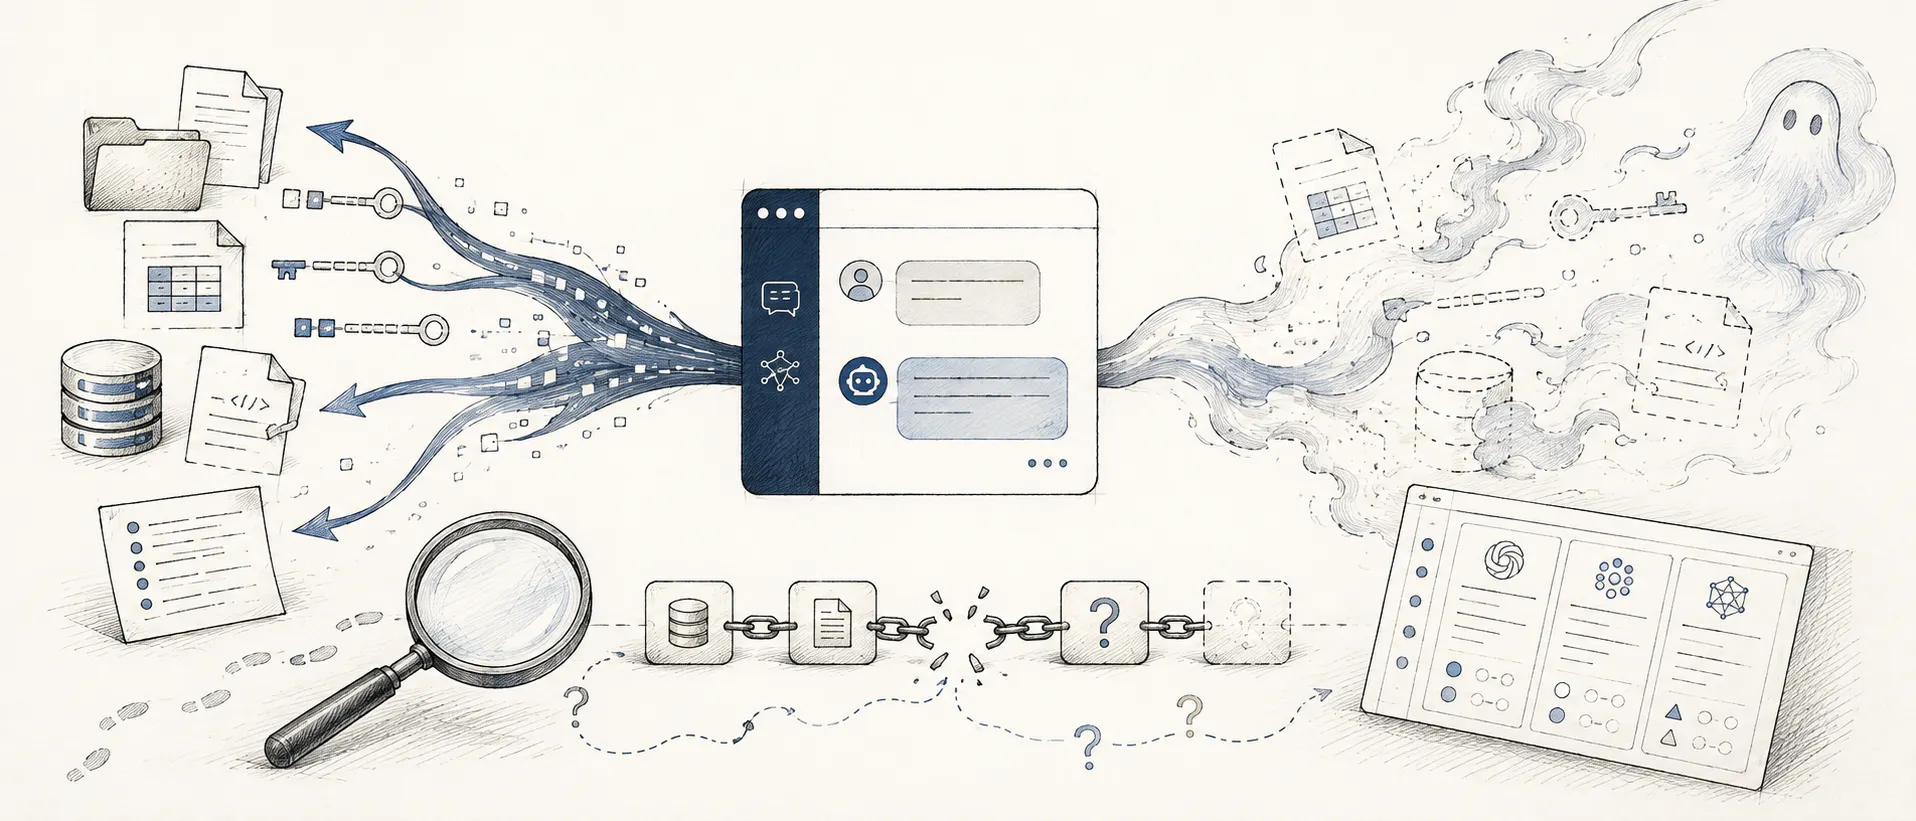
A firsthand look at what happens when real account memory, simulated tools, security-shaped hallucinations, and unreliable provenance all meet in the same AI application.
A shorter, screenshot-free version of this research was previously published by SecurityBrief. This is the longer technical case study: the prompts, the model disagreements, the screenshots, and the parts I still cannot conclusively explain.
I started this experiment expecting to test a fairly familiar class of GenAI problems: prompt leakage, weak guardrails, and the tendency of models to invent convincing answers when pushed outside their actual capabilities.
What I ended up with was harder to classify.
One model displayed instruction-like internal rules.
Another surfaced genuine information associated with my account.
The models then began producing database records, internal-looking routes, API-key-shaped values, logs, PII-shaped fields, and Zscaler-themed infrastructure.
At different points, some of this material was described as hypothetical or simulated.
Later, another model said some of...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE