The Systems Around the Model: What Enterprise Architecture Gets Wrong
One discussion that comes up again and again in enterprise AI is model selection. Teams spend a lot of time comparing GPT with Claude, debating closed source versus open source models, and discussing whether a larger context window will make a noticeable difference.
Those are all useful questions, but they are rarely the first thing I worry about anymore. A more practical question is whether the assistant can actually see the information it needs to give a reliable answer in the first place.
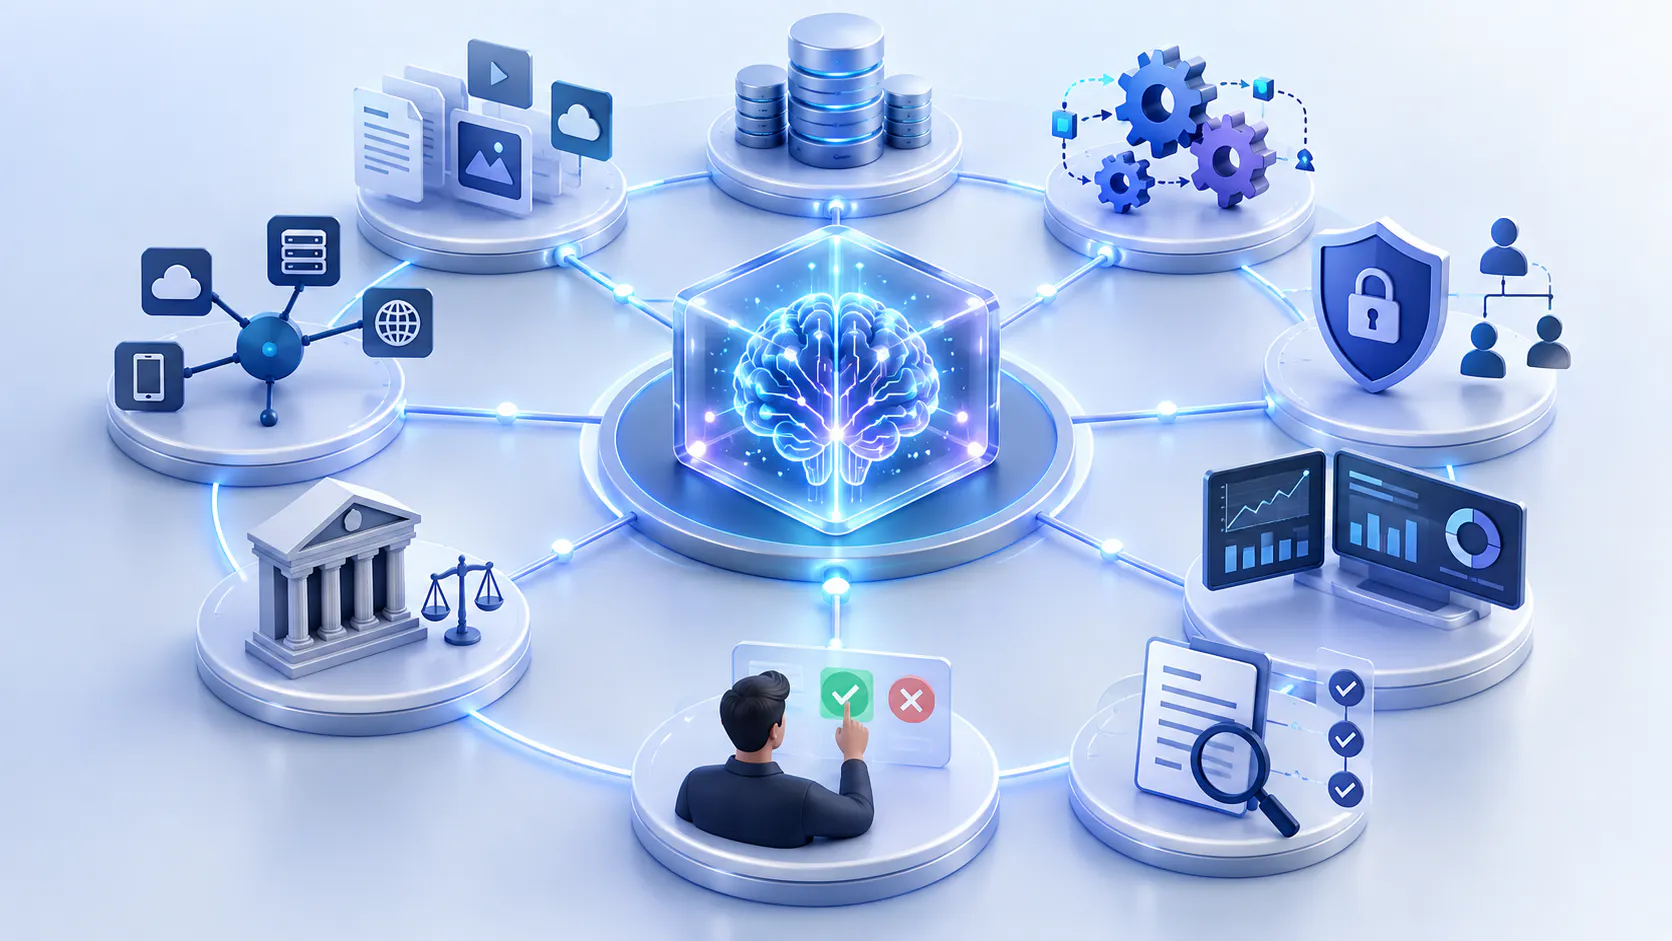
That became much clearer to me while working on API centric systems rather than purely AI systems. In enterprise environments, information is rarely stored in one clean and perfectly maintained location. It is spread across API specifications, internal services, configuration files, runbooks, product documentation, tickets, databases, and sometimes even knowledge that exists only in the heads of a few experienced engineers.
The bigger problem is that all...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE