My RAG Pipeline Found the Right Documents. Then the Reranker Buried Them.
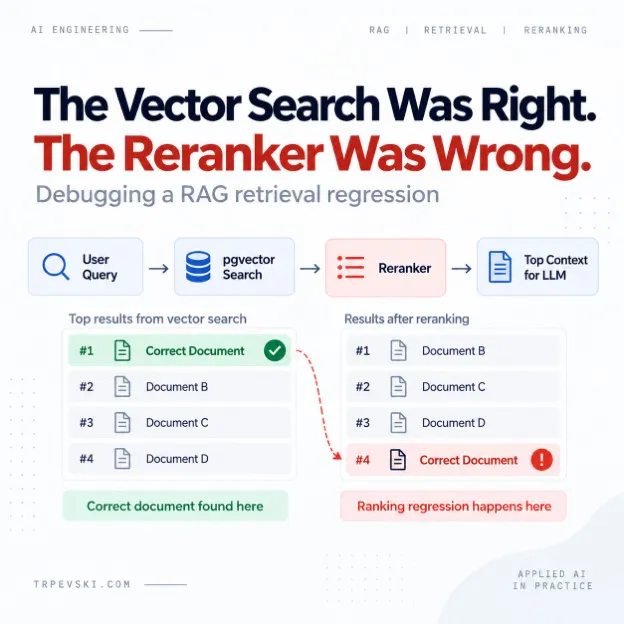
I debugged a RAG pipeline where vector search found the right documents, but the reranker pushed them down. Here’s what was going wrong.
The Vector Search Was Right. The Reranker Was Wrong.
I was asked to inspect a RAG pipeline that wasn’t consistently returning the right context.
The architecture looked normal. Documents were embedded and stored in PostgreSQL with pgvector. A similarity search retrieved candidate chunks, then a reranker reordered them before the final context was sent to the LLM.
Nothing unusual there.
Query ↓Embedding ↓pgvector similarity search ↓Candidate documents ↓Reranker ↓Top documents ↓LLM
The obvious assumption was that retrieval needed improvement.
It didn’t.
Once I started looking at the pipeline stage by stage, I found that pgvector was already retrieving the correct documents.
We were finding the right documents, then losing them.
Looking at retrieval before looking at the LLM
When a RAG system produces a bad answer, it’s...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE