Multi-tenant agent memory isolation is a filtering problem, not a ranking problem
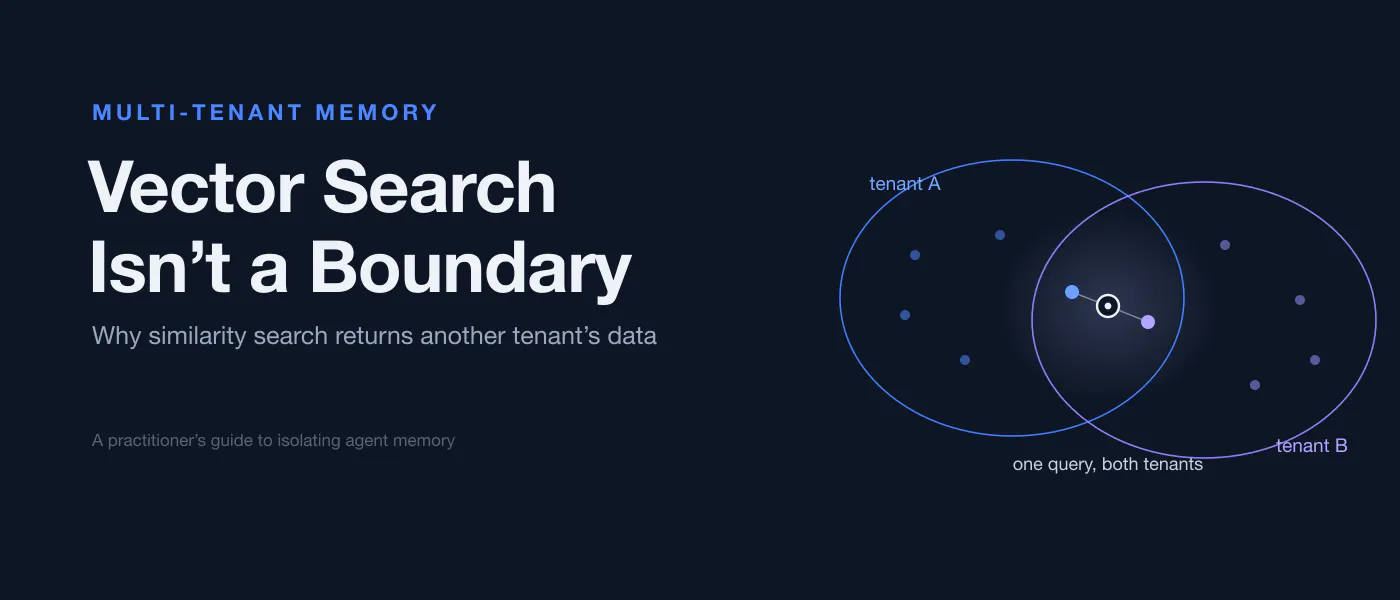
Multi-tenancy in agent memory usually gets treated as a config detail. Add a tenant_id, filter on it, move on. The problem is that filtering and vector search are two different operations, and the order you run them in determines whether isolation is deterministic.
An approximate nearest neighbor (ANN) search returns the k closest vectors it can find in the time budget you gave it. If the index holds every tenant's memories and you count on a tenant's own rows ranking highest, your isolation is a statistical tendency. It holds until two customers in the same vertical write near-identical facts: "primary datastore is Postgres", "we deploy to eu-central-1", "on-call rotation is weekly". Those embed to almost the same vector. The ranking cannot separate tenant A's copy from tenant B's, because nothing semantic separates them.
Relational databases solved this twenty years ago with row-level security. Storing embeddings does not change the problem....
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE