Bloom Filters in Claims Processing: False Positives, Memory Trade-Offs, and Safe Lookups
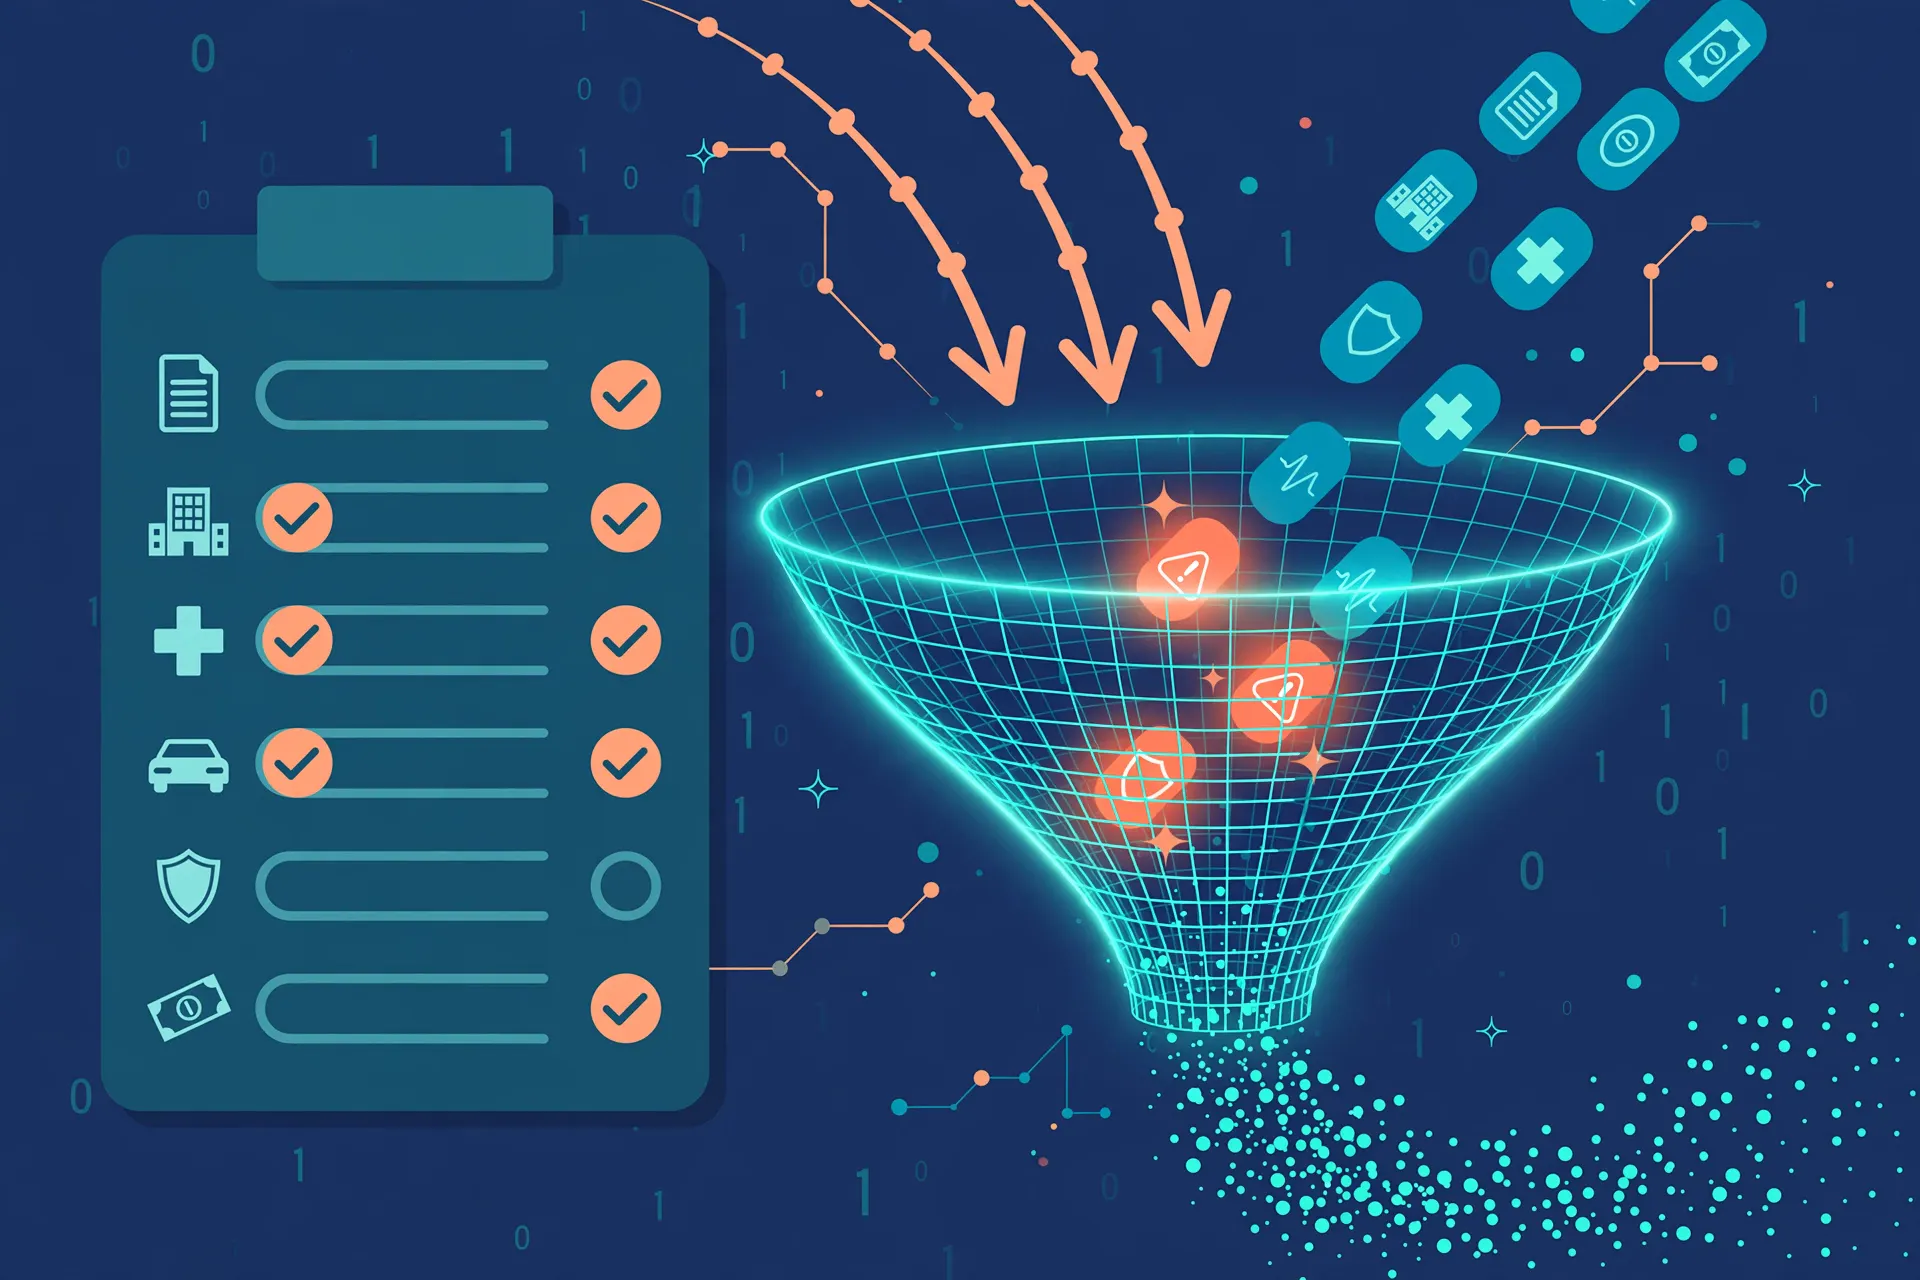
A Bloom filter can be wrong in only one direction — which is exactly what can let a claims system skip an expensive lookup for the honest majority.
Consider the most thankless check a claims system runs: deciding, for every new claim, whether it has been seen before. At first notice of loss, an insurer wants to know whether this VIN, this claimant, this device, or this exact document has already appeared — in its own claims history, in a cross-industry fraud and duplicate database, or on a watch list. Most claims are legitimate and new, so in a design like this the check would usually come back “no.” Proving “no” can be expensive. It can mean querying very large datasets, sometimes through an external shared service that adds cost and latency. Multiply that by every incoming claim, and a pipeline can spend real time and money confirming, over and...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE