Your RAG Pipeline Dies on Real Documents: Here's Why
Every retrieval demo you have ever seen used clean input. Markdown files, a folder of blog posts, maybe a tidy CSV. You chunk it, embed it, query it, and the answers come back right.
Then somebody points it at the documents the business actually runs on. A supplier contract in PDF. A quarterly report where the numbers live in a table spanning two pages. A scanned form somebody signed, photographed, and emailed.
The pipeline does not error. That is the problem.
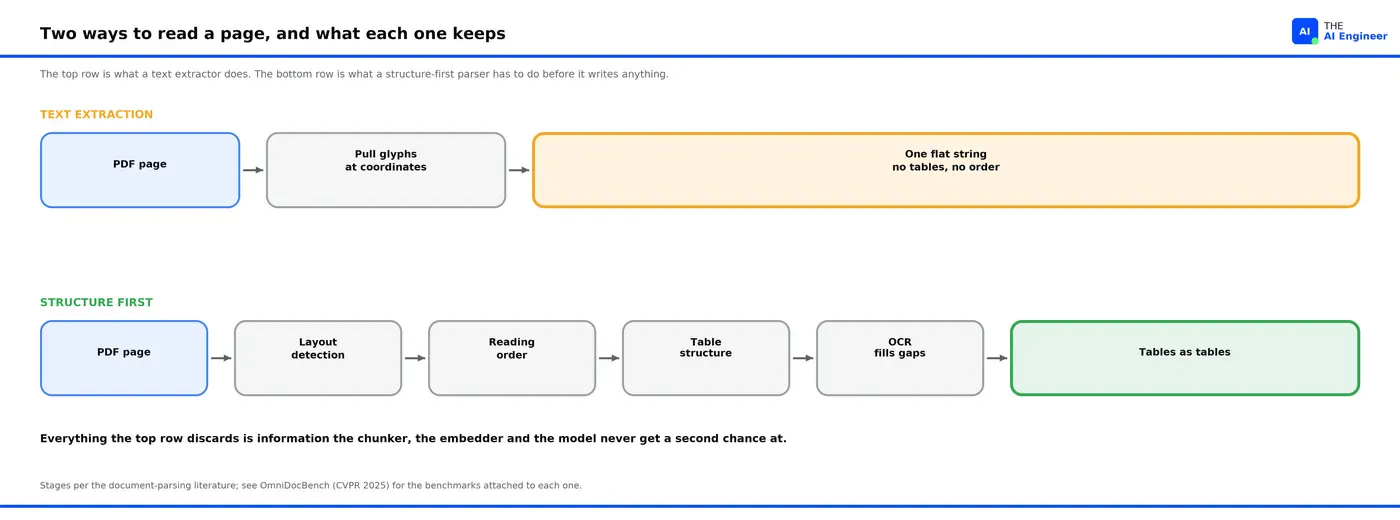
It returns an answer, confidently, built from text that arrived in the wrong order, from a table that got flattened into a single line of digits with no column headers attached. Nothing in your stack knows this happened. Your evals pass, because your evals were written against the clean corpus too.
This is the least glamorous version of the demo-to-production gap. Your retrieval layer sits downstream of a parser,...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE