Your Agent Retries Because It Can't Tell a Timeout From a Failure
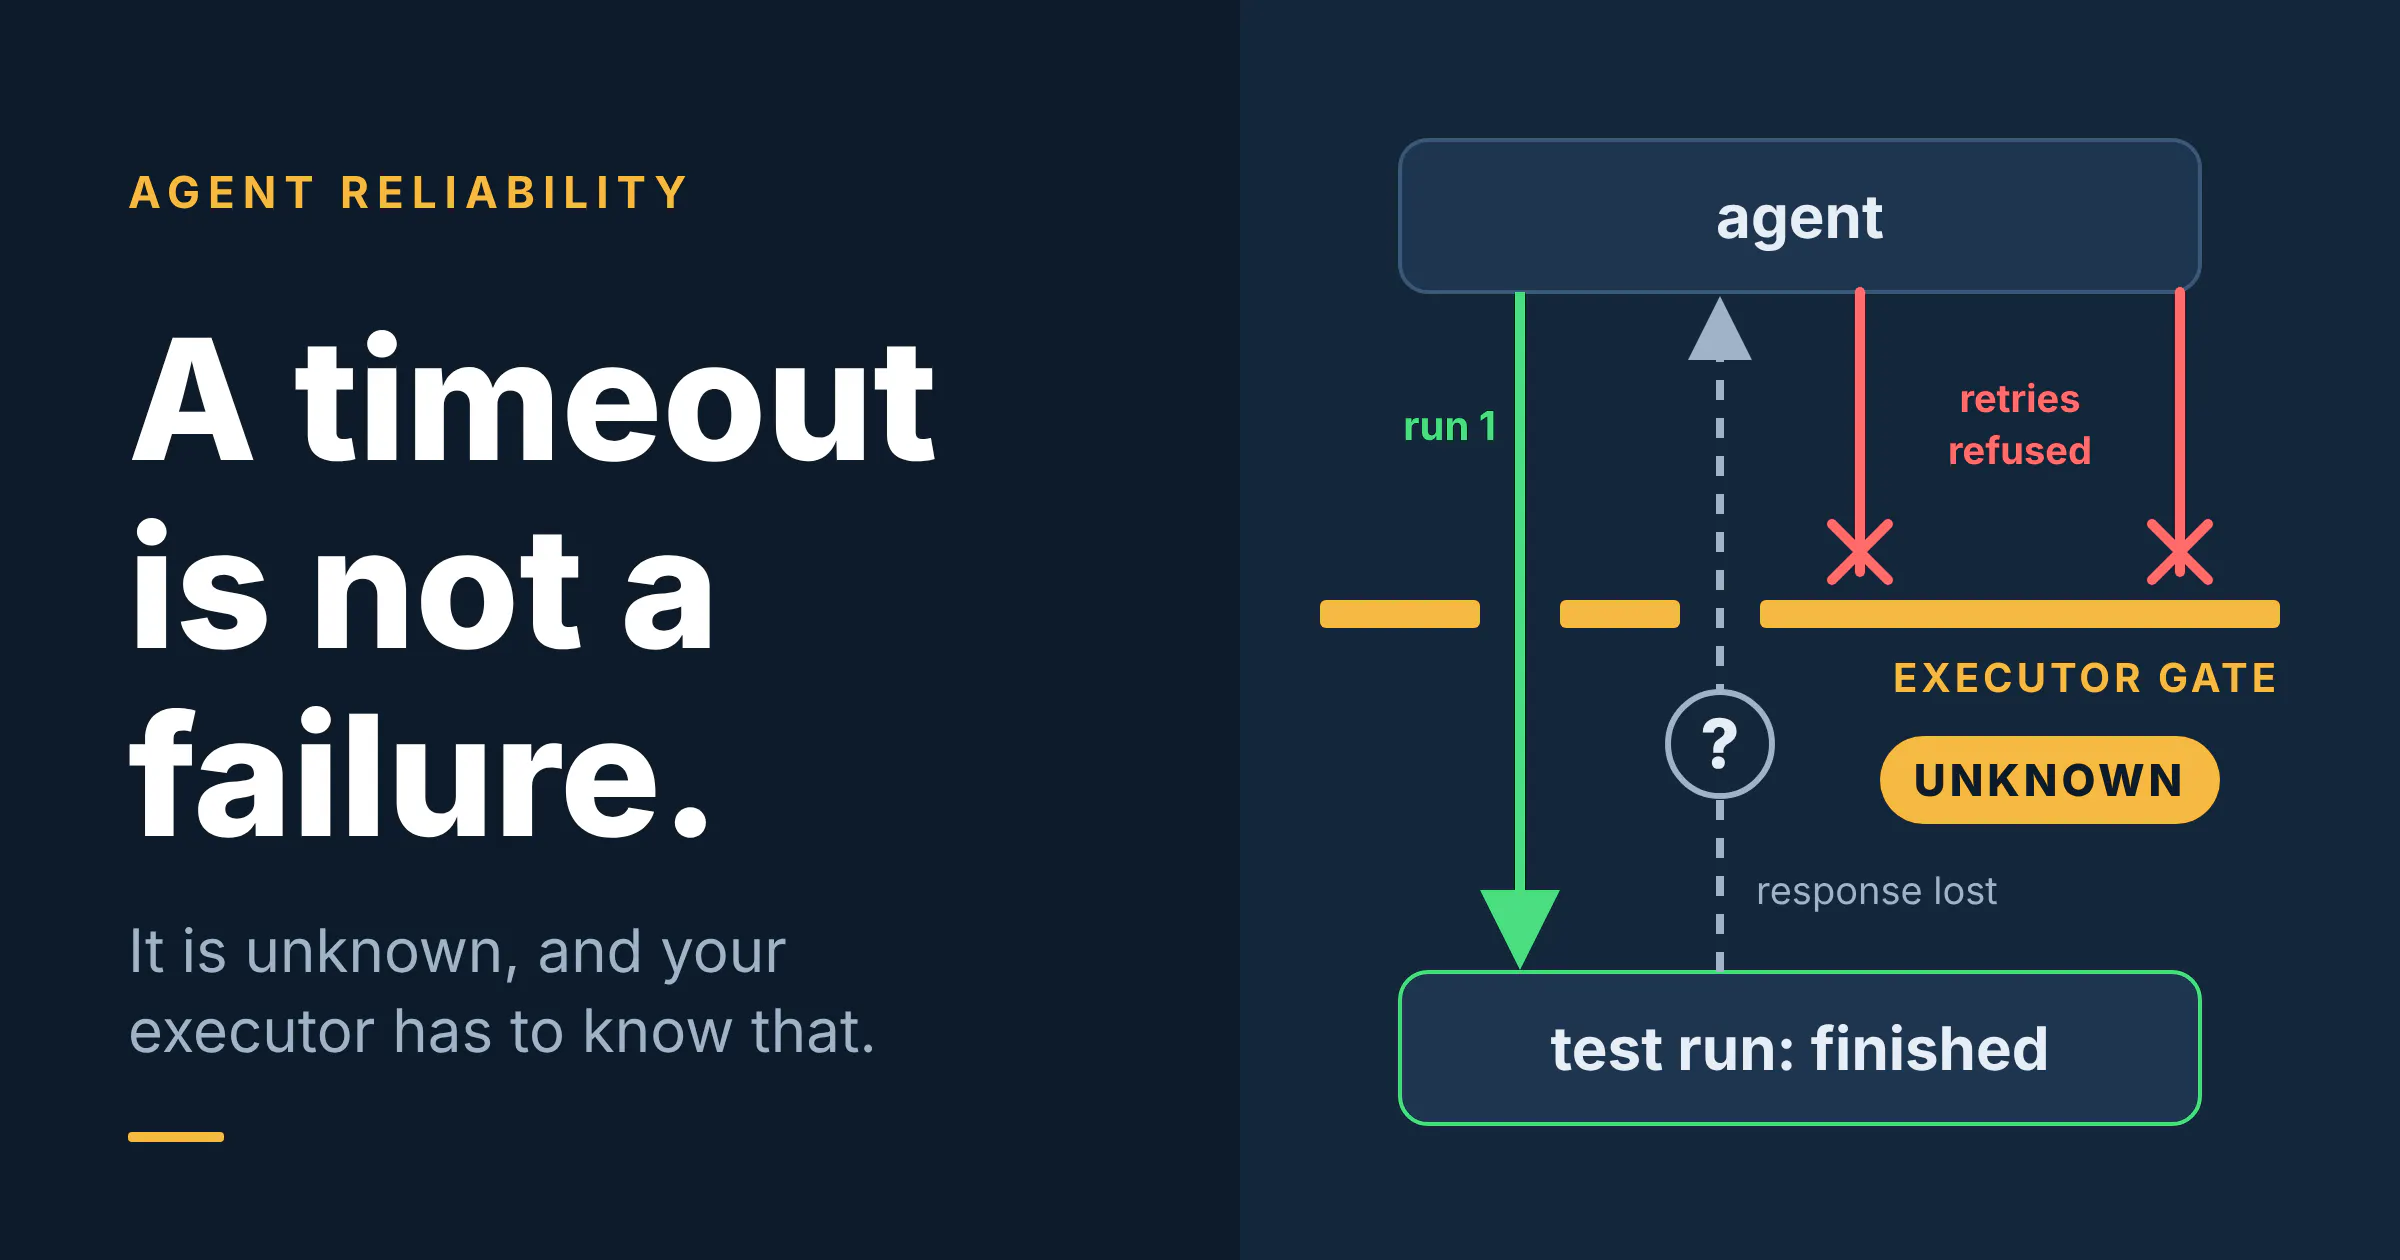
TL;DR: My agent hit a timeout, treated it as a failure, and re-ran a task that had already finished. It correctly diagnosed every error it saw and kept retrying anyway. Understanding a failure does not constrain what an LLM does next, so the constraint has to live in the execution layer, and that layer needs a state most retry logic lacks: unknown.
I have since turned the fix into a small open-source gate, with a demo you can run in a few seconds: Harness-Engineering on GitHub. This article explains why it works the way it does.
The task had already completed
I am building an agent that reviews automated test coverage. It executes test scripts, then compares what they exercise with the application design, the source code, and the acceptance criteria of the user stories. Its job is to find requirements that look implemented but have no meaningful...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE