Why ROUGE Lies About Your LLM Outlines and How Grounded Fine-Tuning Fixes It
Key Takeaways
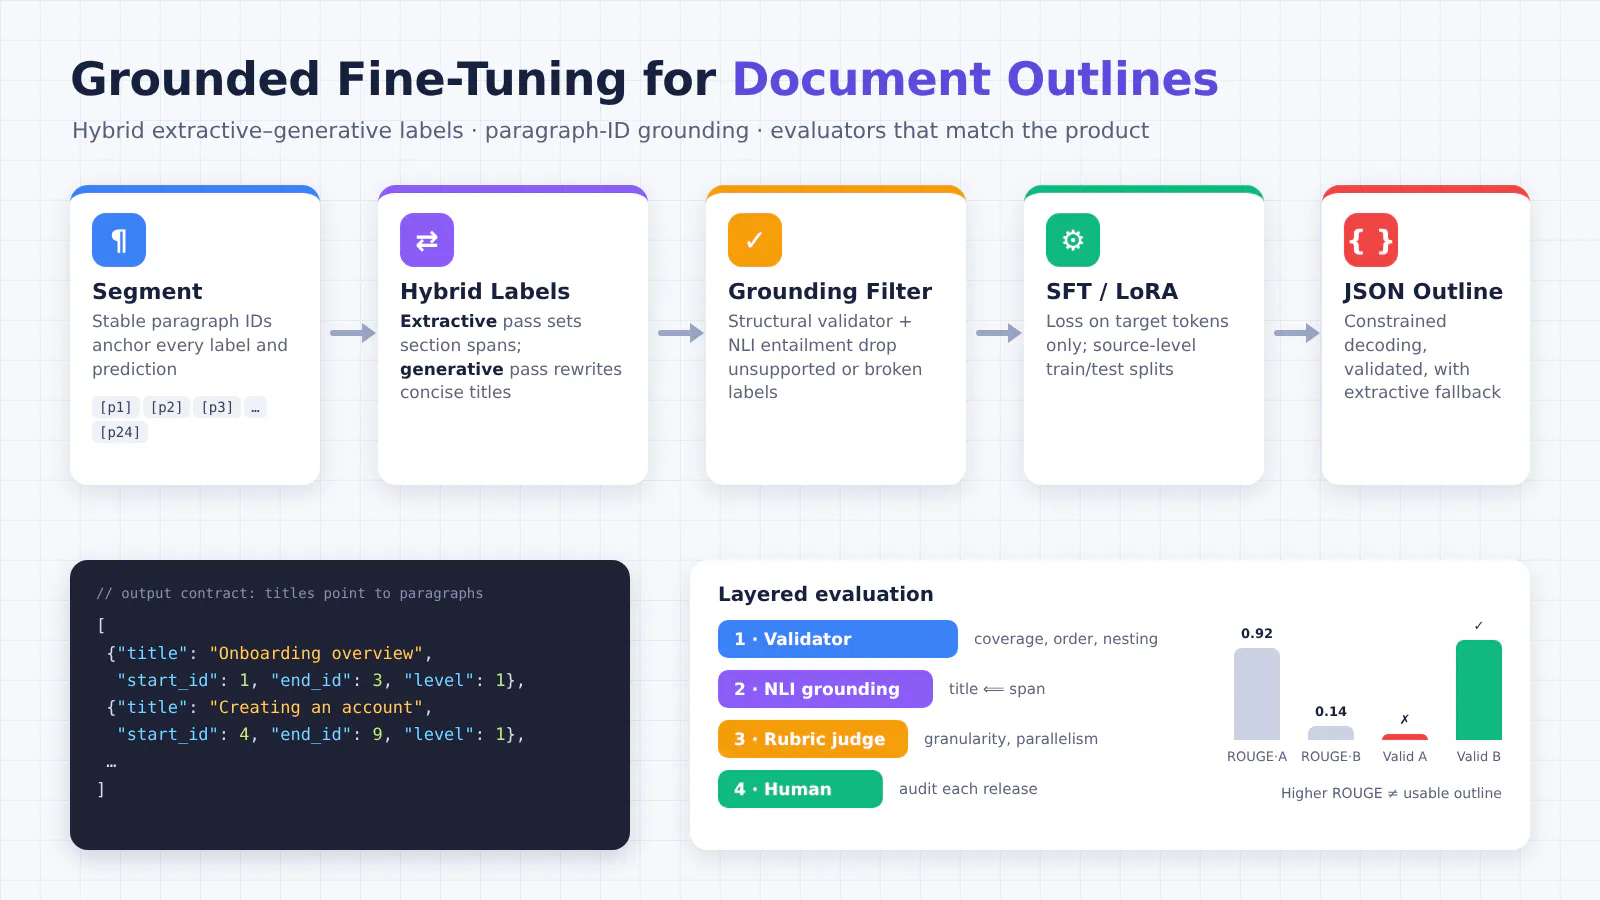
- The outline should be handled as structured model output: a title paired with paragraph IDs, rather than as text. That small shift makes it machine-checkable for grounding.
- The hybrid labeling should be compared to an extractive-only and to a generative-only labeling on the same held-out data set when possible; the current version of Table 3 summarizes evidence from the literature rather than gives us results of this comparison.
- Noisy span boundaries require data-quality checks; without the audit-trail experiment, comparisons of model size should be treated as hypotheses rather than facts.
- Evaluate in layers: The structural and basic analysis, rubric, and human review. We will do comparisons using ROUGE and BLEU against a single human reference, which is to put forth penalties to the correct paraphrase, which in turn will rank the faulty in terms of structure.
- Release a measure like (for example, share of documents with acceptable outlines)...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE