Why Better Search Recall Did Not Mean Better RAG Answers
A paired 230-question experiment with the same BM25 implementation, two tool interfaces, and a result that made me inspect the evidence actually delivered to the model.
Disclosure: I build Minimal RAG, the personal research project discussed here. This article was prepared with AI assistance from recorded experiments and checked against the linked results. It adapts my previously published project case study; it is not independent validation of the project.
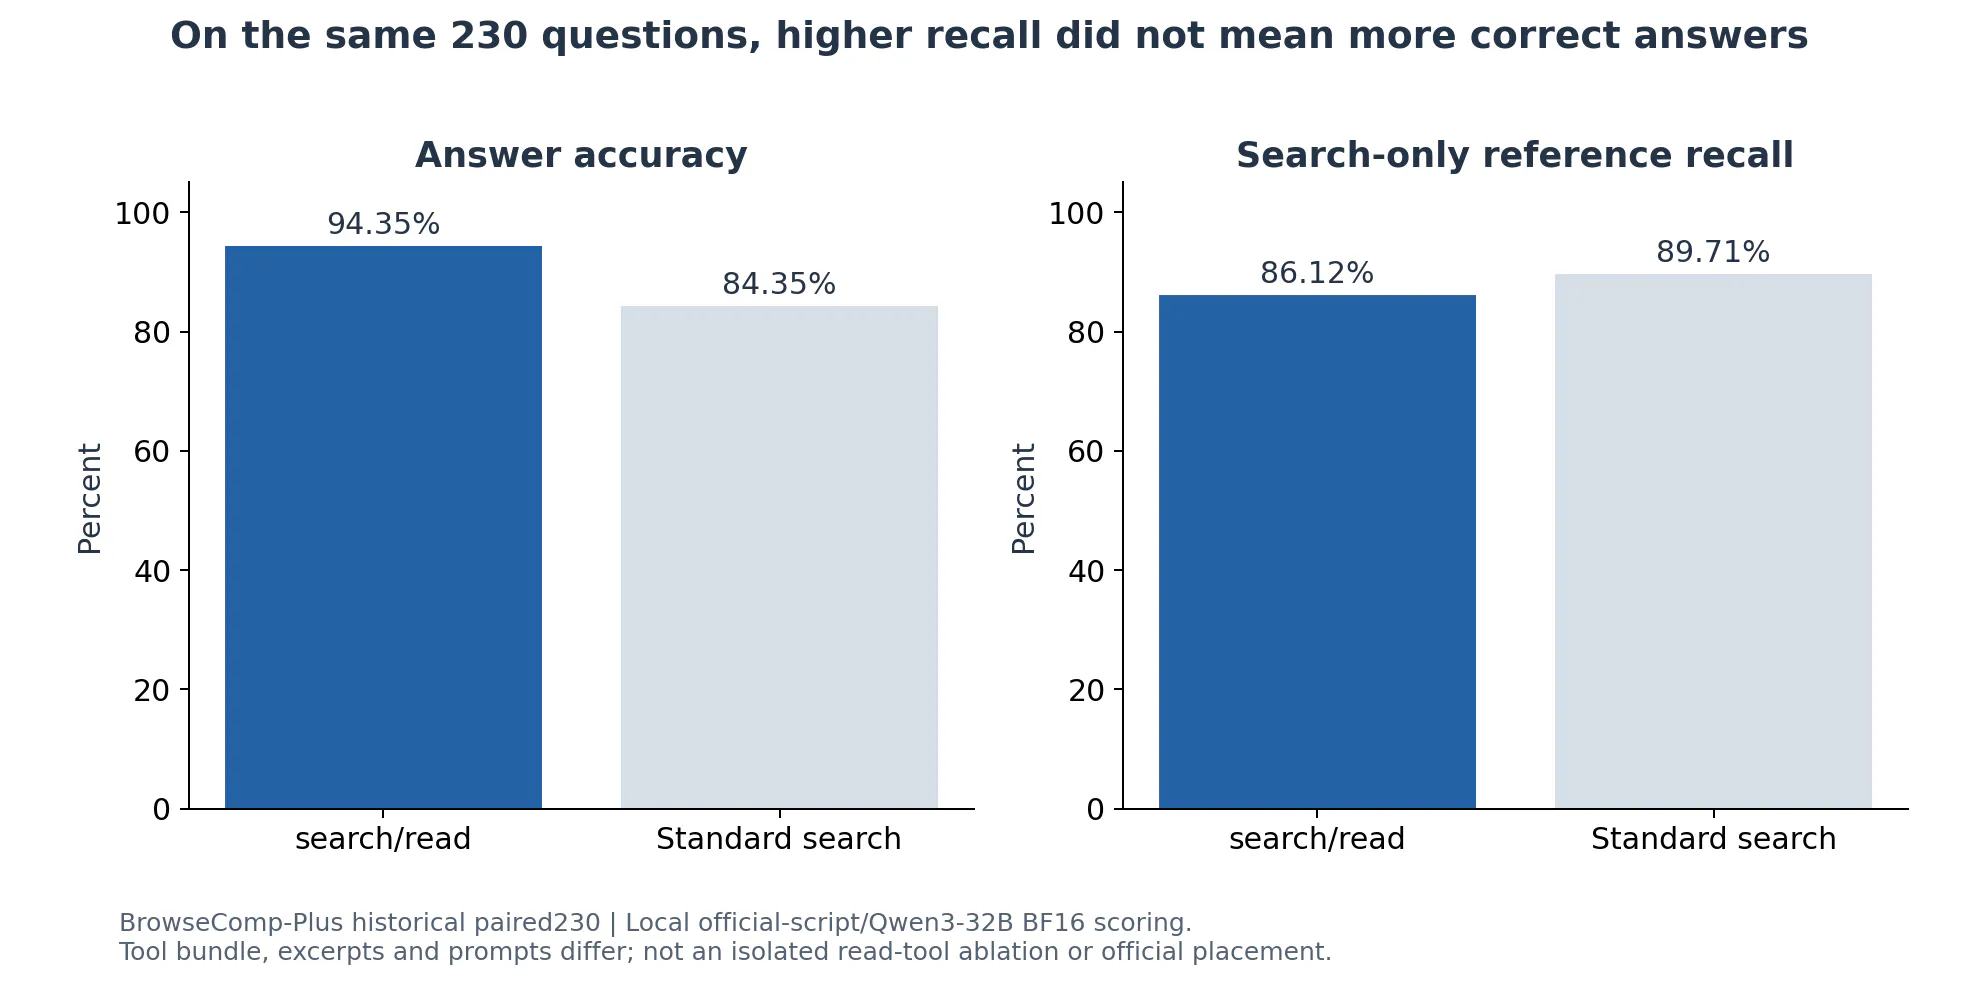
Both versions used BM25. The version that returned more of the reference-document IDs answered fewer questions correctly.
That was the interesting result in a historical comparison on 230 BrowseComp-Plus questions. My project's search/read interface answered 217 correctly. A standard search interface answered 194. Search-only reference-document recall moved in the opposite direction: 86.12% for the project interface and 89.71% for the standard one.
The comparison made me pay more attention to the boundary between finding a document and delivering its useful passage....
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE