Tracing Contextual Token Representations Through Transformer Layers
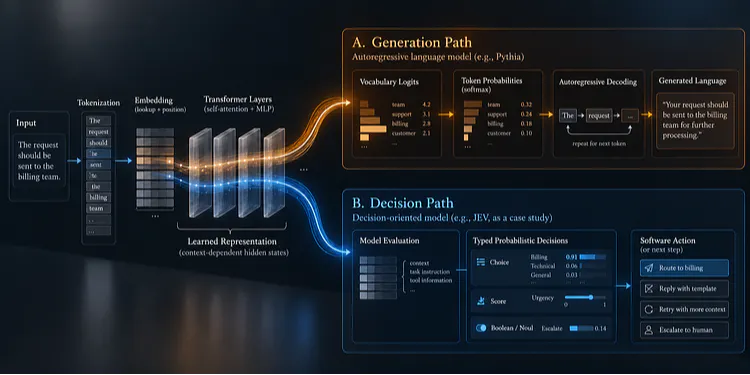
The same token can begin with the same embedding and develop different representations. Calling a word “a vector” hides this transformation: inside a Transformer, the initial embedding is only the starting point of a computation shaped by context. Here, light refers to weight in one sentence and color in the other. By holding its token ID and position fixed while changing the preceding words, we can follow its hidden state through successive layers. Where does contextual separation emerge — and what happens to it near the output?
Following that transformation requires deciding what counts as a difference. Do we care about the vectors’ directions, their magnitudes, or the distances between them? These measurements capture different properties of the same representations and can reveal different patterns across depth. Understanding how context reshapes a token therefore requires examining both the model’s computation and the measurements we use to describe it.
Using Pythia-160M,...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE