The Hidden Costs of Apache Spark: Why Architecture Matters More Than Compute
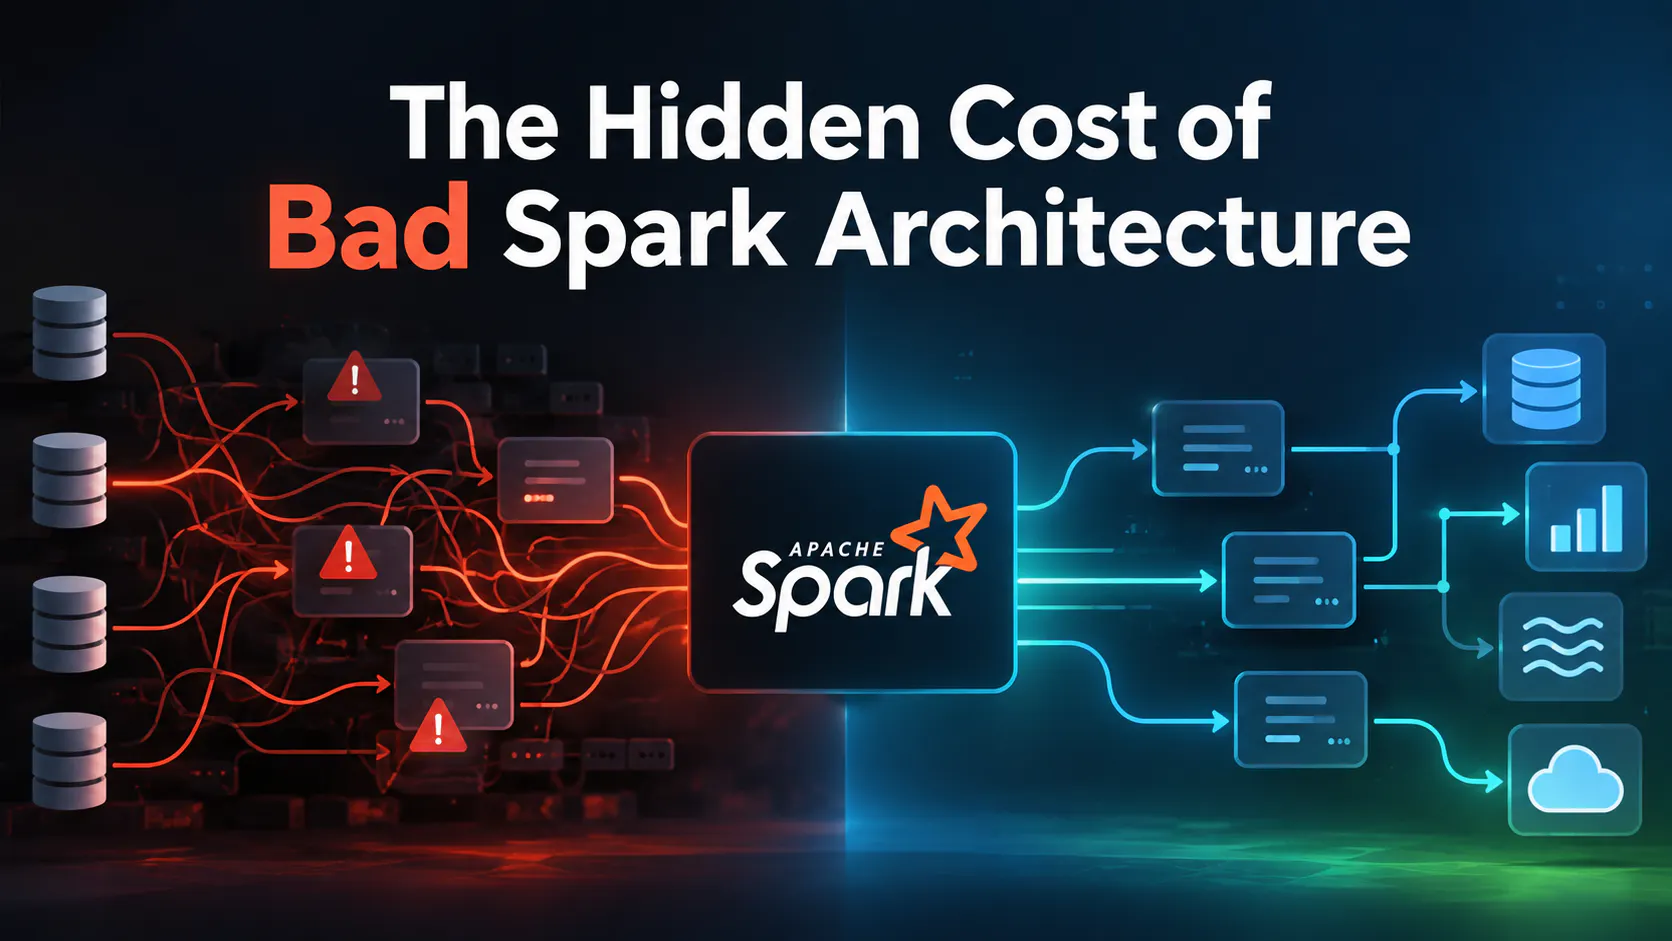
Why adding executors rarely fixes the most expensive Spark problems
A slow Spark job is often treated as a sizing problem: add executors, increase memory, raise shuffle partitions, and try again. That can hide the real issue. The expensive failures I see in Spark architectures usually come from unnecessary shuffles, skewed joins, poor file layout, stale or missing statistics, oversized scans, and pipelines designed without regard for the physical execution plan. Spark 4.0.4 can mitigate several of these problems through Adaptive Query Execution (AQE), but AQE is not a substitute for sound data layout and query design. This article presents an architecture-first way to diagnose Spark cost before reaching for more compute.
The Cluster Is Usually the First Suspect
When a Spark workload misses its SLA, the first conversation often starts with infrastructure. How many executors did we have? How much memory? Should we increase executor cores? Would a larger...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE