

The Evolution of LLMs, Explained Through What We Train Them to Do
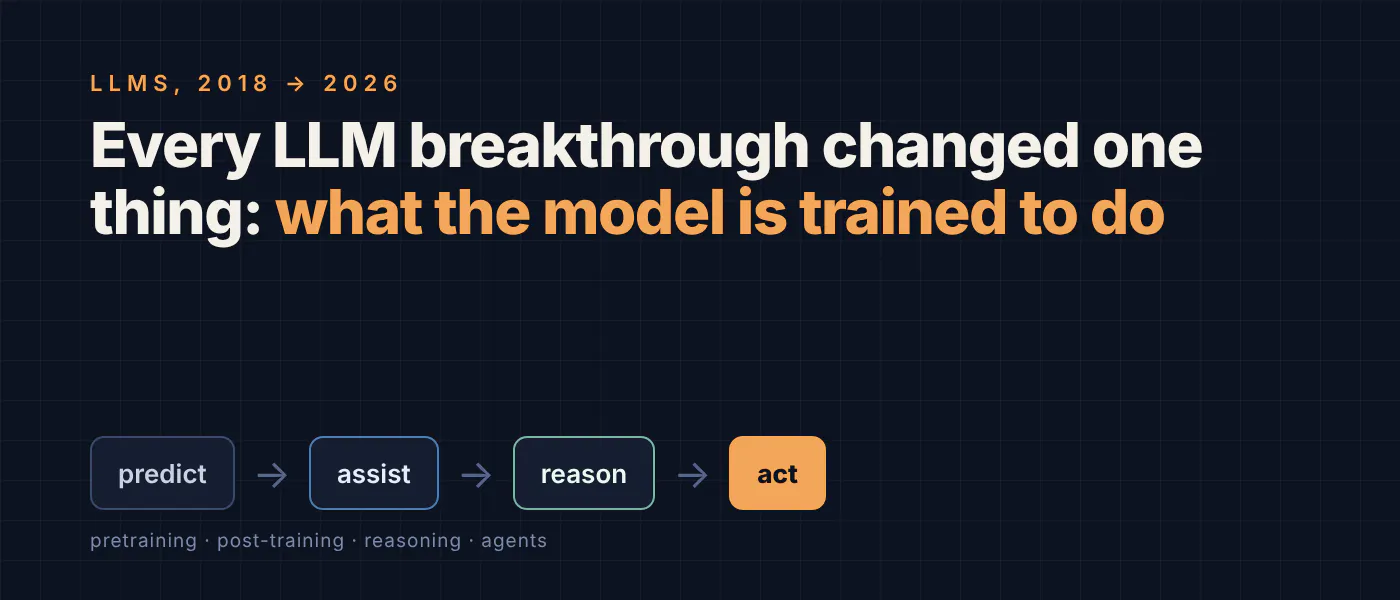
TL;DR: Every leap in LLMs, from GPT-1 to today's agents, came from changing one thing: what the model is trained to do. Next-token prediction gave models knowledge. Post-training made them assistants. Reinforcement learning made them reason. Tools made them agents. Underneath it all, the real engine is data designed to teach the right objective.
Every few weeks, a new LLM launches and the feed calls it a revolution. Taken one at a time, the launches look like noise.
There is a simpler way to read the story. Each big step answered one question: what should we train the model to do?First the answer was "predict the next word." Then it became "be a helpful assistant," then "think before you answer," and now "take actions until the job is done." Each step kept everything before it and added one idea on top. This mental model helps me make sense of...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE


