TECH NEWS
EU-Philippines Trade Deal Nears Final Agreement, but Key Digital Rules Remain Unpublished - TechRepublic
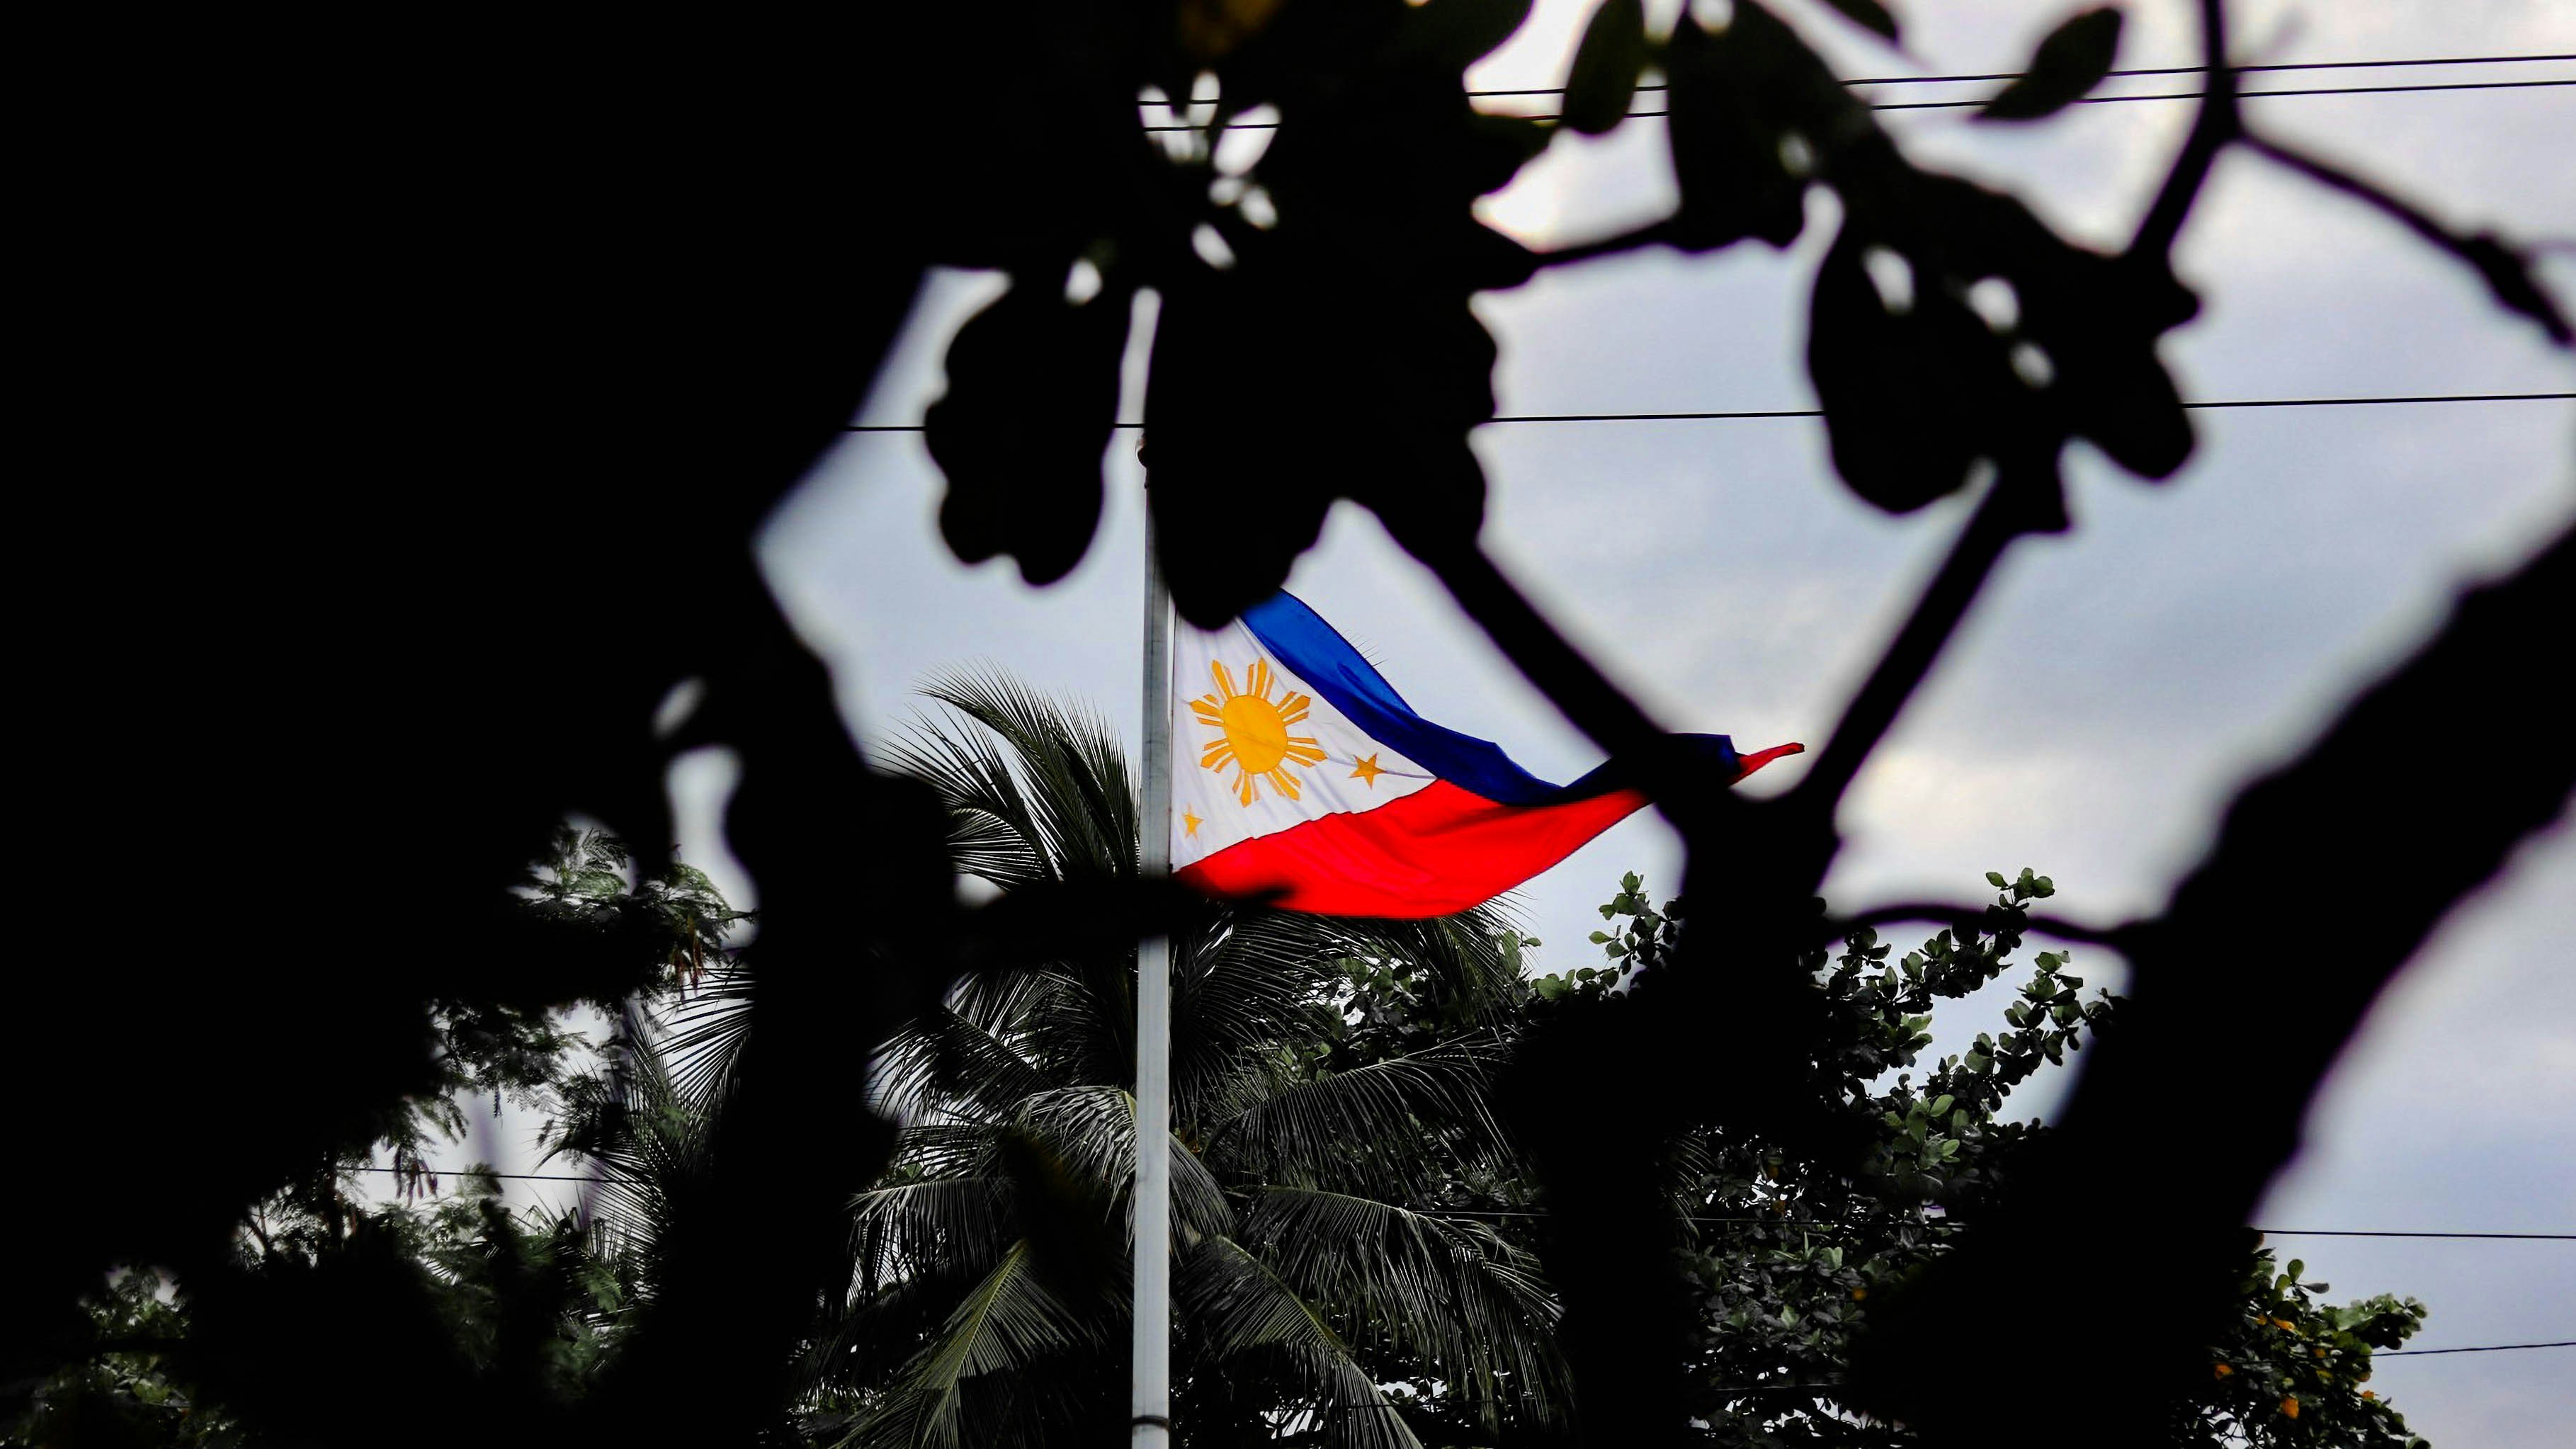
The EU-Philippines trade deal could reshape digital commerce, technology procurement, and cross-border market access. Image: iSawRed/Unsplash The EU and Philippines are nearing a trade pact that could reshape digital commerce, cloud access, and public-sector tech procurement. Sep 25, 2026 We may earn from vendors via affiliate links or sponsorships.