SenseNova-U1-8B GGUF: Run Multimodal AI on 8GB VRAM
Overview
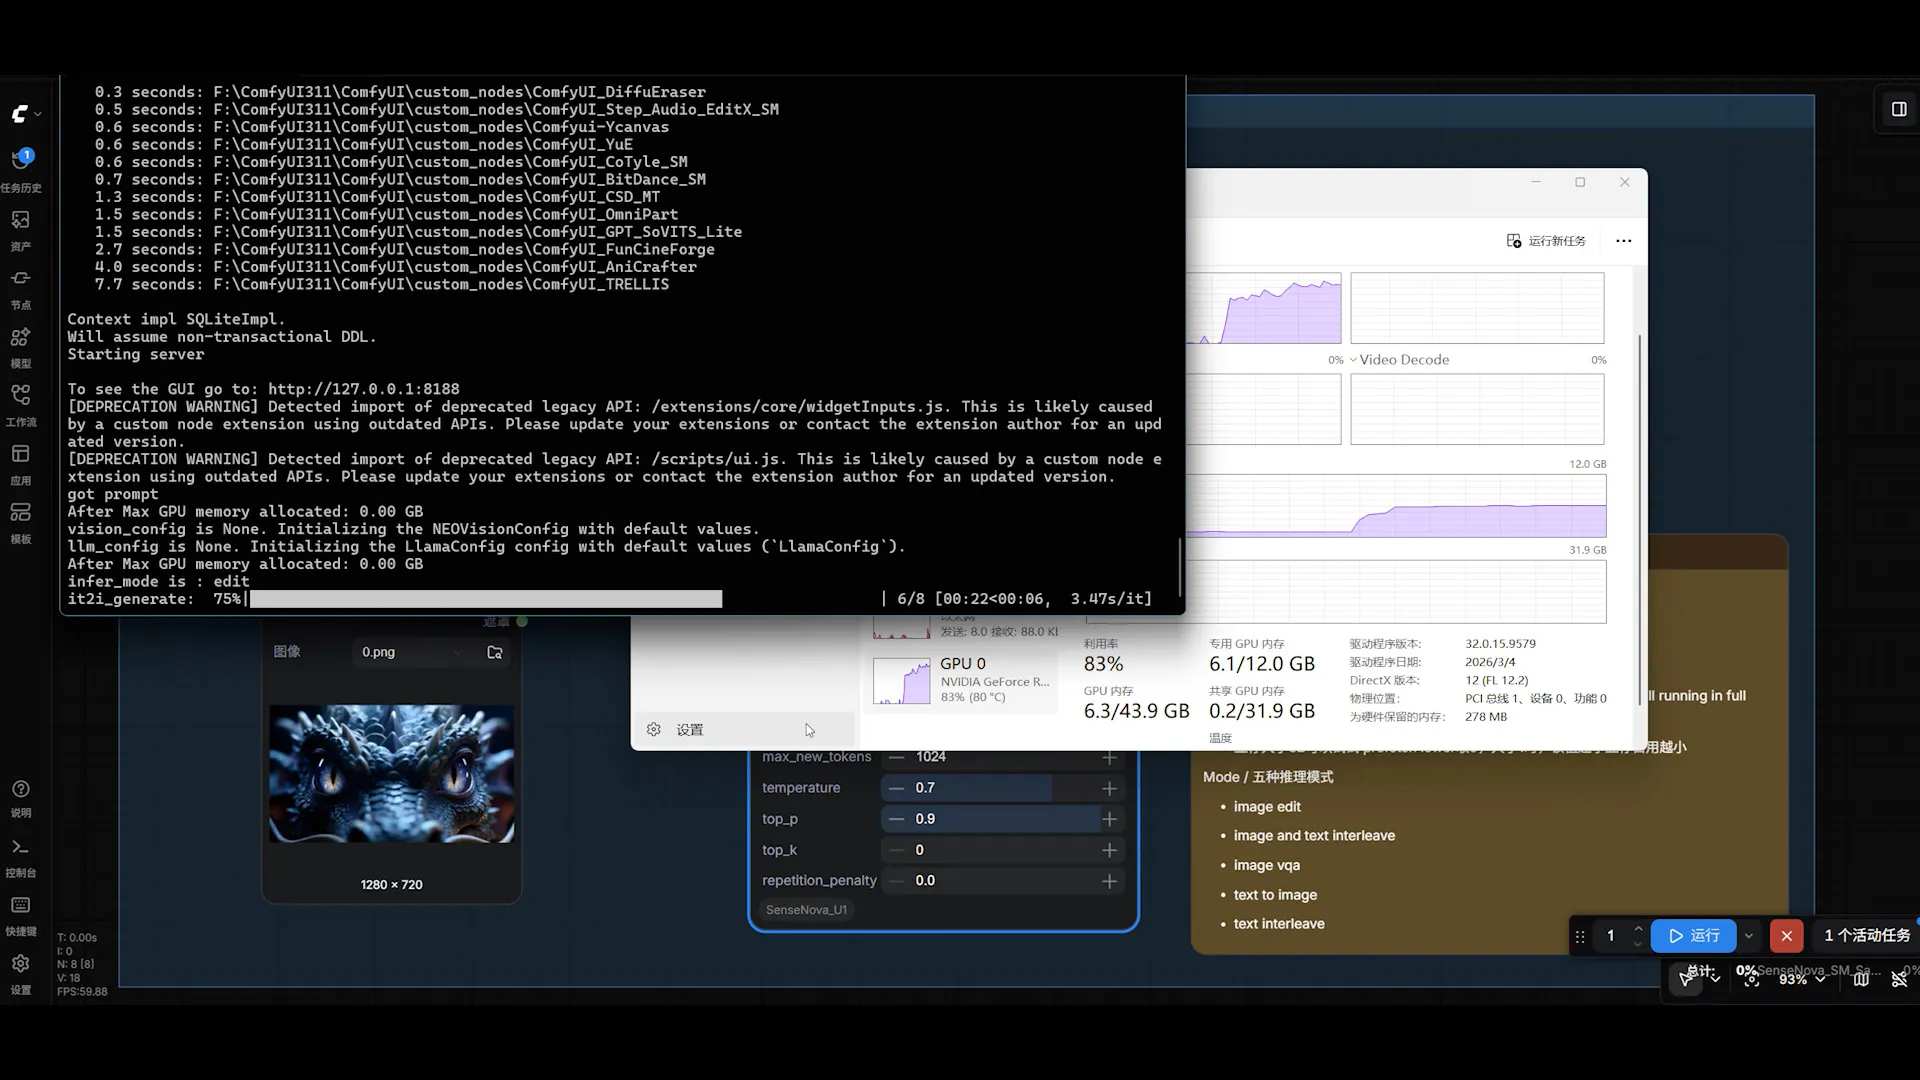
SenseNova-U1-8B-MoT-Merger-gguf is a quantized GGUF format version of the SenseNova-U1 multimodal model maintained by smthem. This model operates as an 8-billion parameter multimodal transformer capable of both understanding and generating content across text and image modalities using the NEO-unify architecture. The critical detail before using this model is that it requires ComfyUI integration with specific VRAM optimization for 8GB GPU configurations, making it accessible on consumer-grade hardware. The GGUF quantization format enables efficient inference through quantization-based compression, with Q4 and Q6 quantization variants available. The model supports a "think" mode that enables extended reasoning capabilities, allowing it to process complex prompts with chain-of-thought processing before generation. You will interact with this model through the ComfyUI node system rather than standard Python libraries, requiring familiarity with the ComfyUI workflow paradigm.
Best use cases
Text-to-image generation with reasoning requirements.This model excels when you need to generate images from detailed text...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE