Qwen3.8-27B-DFlash2: A Guide to Faster Qwen Inference
Overview
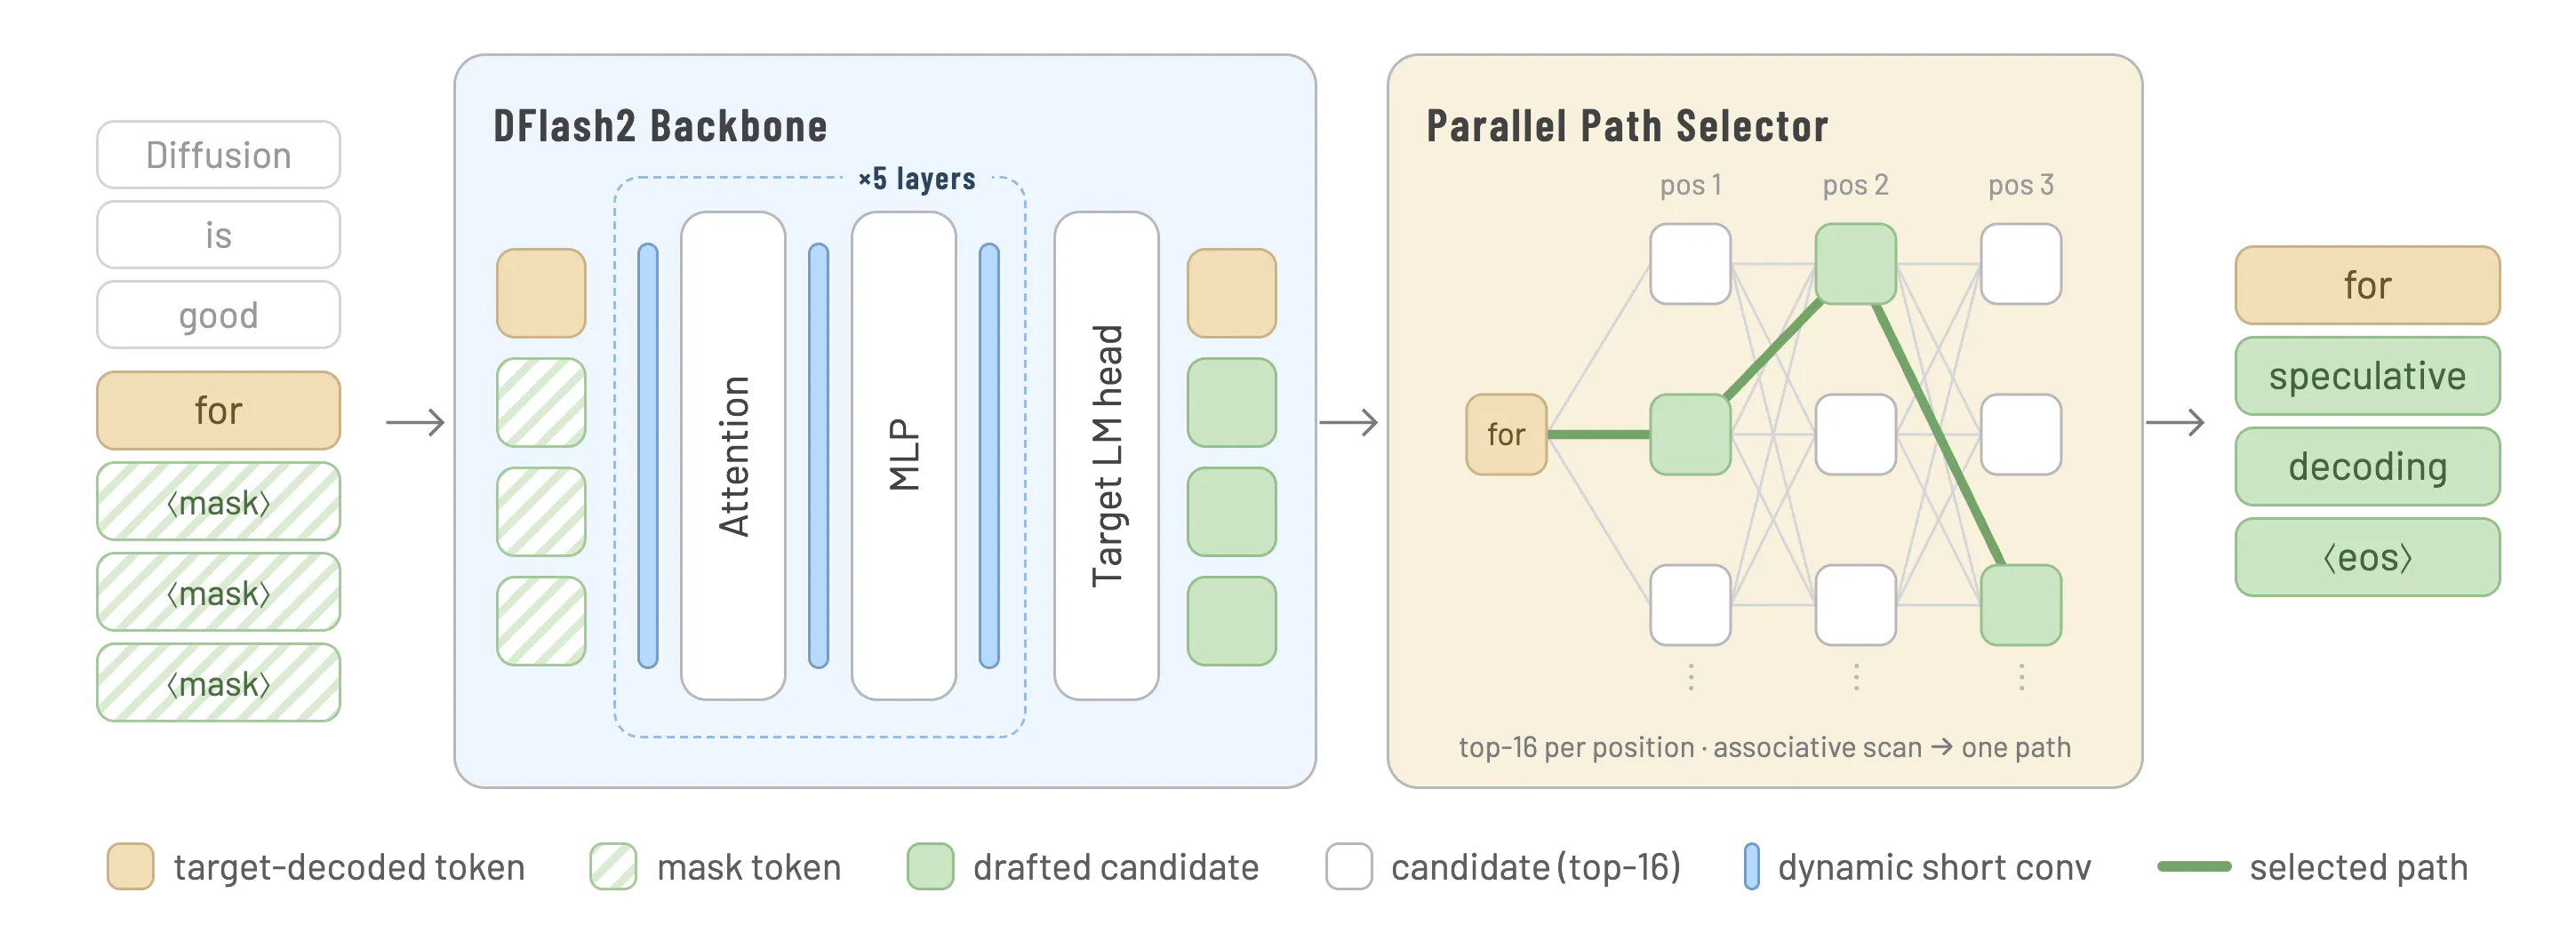
Qwen3.8-27B-DFlash2 is a speculative decoding draft model maintained by z-lab that accelerates inference for the base Qwen/Qwen3.8-27B model. This is not a standalone language model—it functions exclusively as a drafter component within speculative decoding servers like SGLang or vLLM. The model implements block-diffusion drafting, predicting entire blocks of tokens in a single forward pass rather than one token at a time. It maintains top candidate tokens at every position and uses a lightweight selector to trace a coherent decoding path, with two-tap dynamic convolutions preventing quality degradation toward the end of the block. Decoding is mathematically lossless: greedy sampling produces identical output to the target model, and probability distributions are preserved under sampling. The architecture requires SGLang or vLLM with speculative decoding support to function. The model trains with a context window of 4096 tokens and uses an Apache 2.0 license.
Best use cases
High-throughput inference on reasoning tasks....
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE