Nvidia GR00T 2 Trains Robots With Human Demonstrations
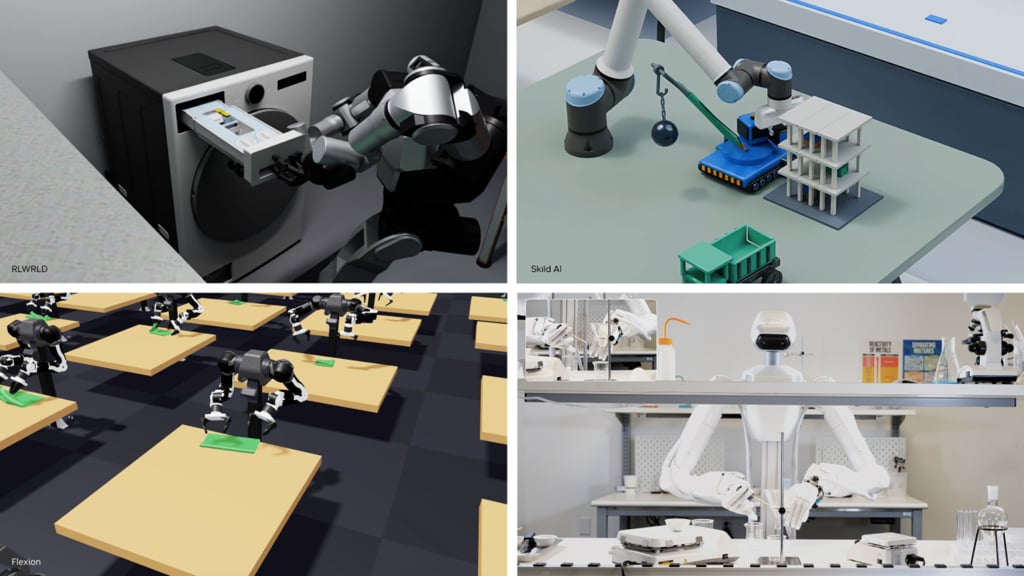
Teaching a robot a new job could start with footage of a person doing it, reducing the need to collect demonstrations on the machine itself.
Nvidia introduced GR00T 2 on Nov. 9 at the Conference on Robot Learning (CoRL) in Austin, Texas. The world action model learns from human videos and robot demonstrations, potentially reducing the task-specific training needed for manufacturing automation. Nvidia’s research page lists code availability for December.
Built on Nvidia Cosmos, GR00T 2 predicts future video and robot actions together, learning how movements change its surroundings. It is designed to work across robotic arms, dexterous hands and humanoids.
Its training data includes 402,730 hours of first-person human video, 10,184 hours of handheld-gripper demonstrations and 23,500 hours of robot teleoperation data. Nvidia is also releasing 100,000 hours of human video and associated motion data through its Human-1M-100K dataset under a license permitting commercial and noncommercial use.
In...
Copyright of this story solely belongs to www.techrepublic.com. To see the full text click HERE