My Glue Job Read Half a CSV From a Strongly Consistent S3
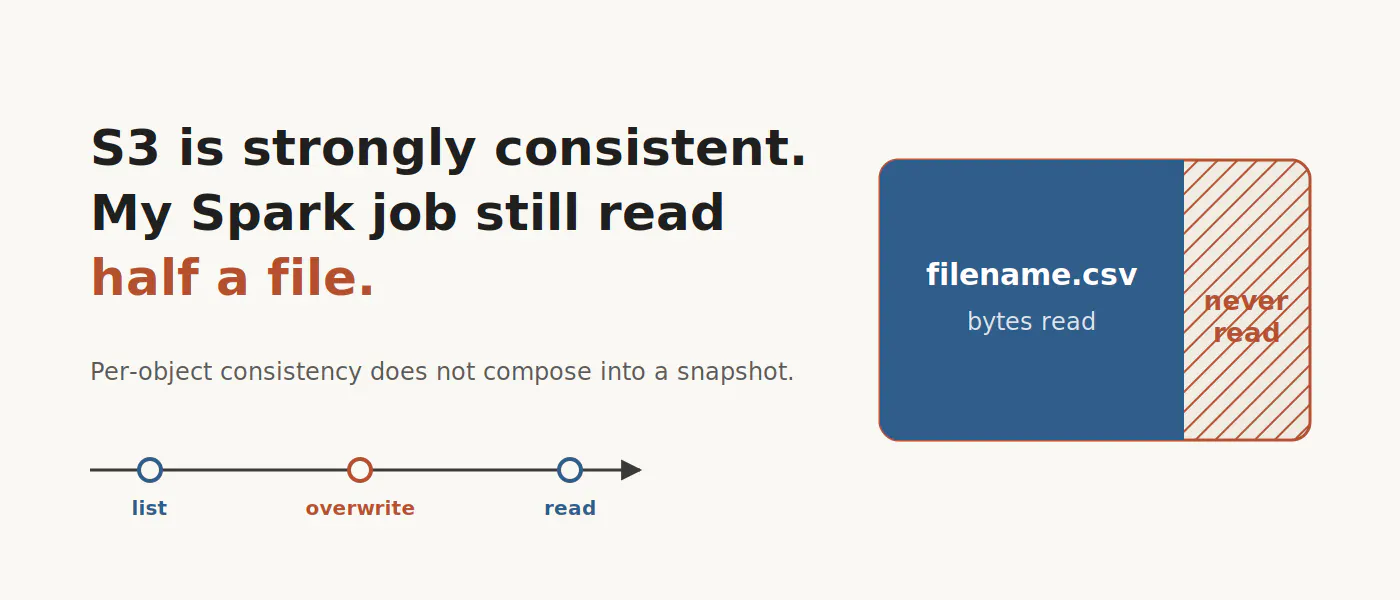
In December 2020, AWS made S3 strongly read-after-write consistent. A PUT shows up in the next LIST. A GET after an overwrite returns the new bytes.
Some months ago a Glue job of mine started dropping records from a 6 MB CSV, and this guarantee sent me looking in the wrong direction.
The job read one object from an S3 prefix. Same key every run, filename.csv, overwritten in place by an upstream process. Most runs were fine. Some came back short. There was no exception. The DataFrame just had fewer rows than the file.
I saved one of the short results. On a rerun the missing records were back.
I assumed Spark had read the object while it was being written. It had not.
I investigated the runs as far as I could, but the evidence was not enough to establish a single root cause. Two mechanisms remained consistent with...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE