LLM Cost Optimization: Your Bill Is an Architecture Problem, Not a Prompt Problem
You launch an LLM feature.
Users like it. Usage grows. Someone adds conversation history. Someone else adds RAG. Then tools. Then retries. Then an evaluator that uses another LLM.
A few months later, finance asks a question engineering teams increasingly have to answer:
Why is the AI bill growing faster than the product?
The first reaction is often to open the system prompt and start deleting adjectives.
That is usually the wrong place to begin.
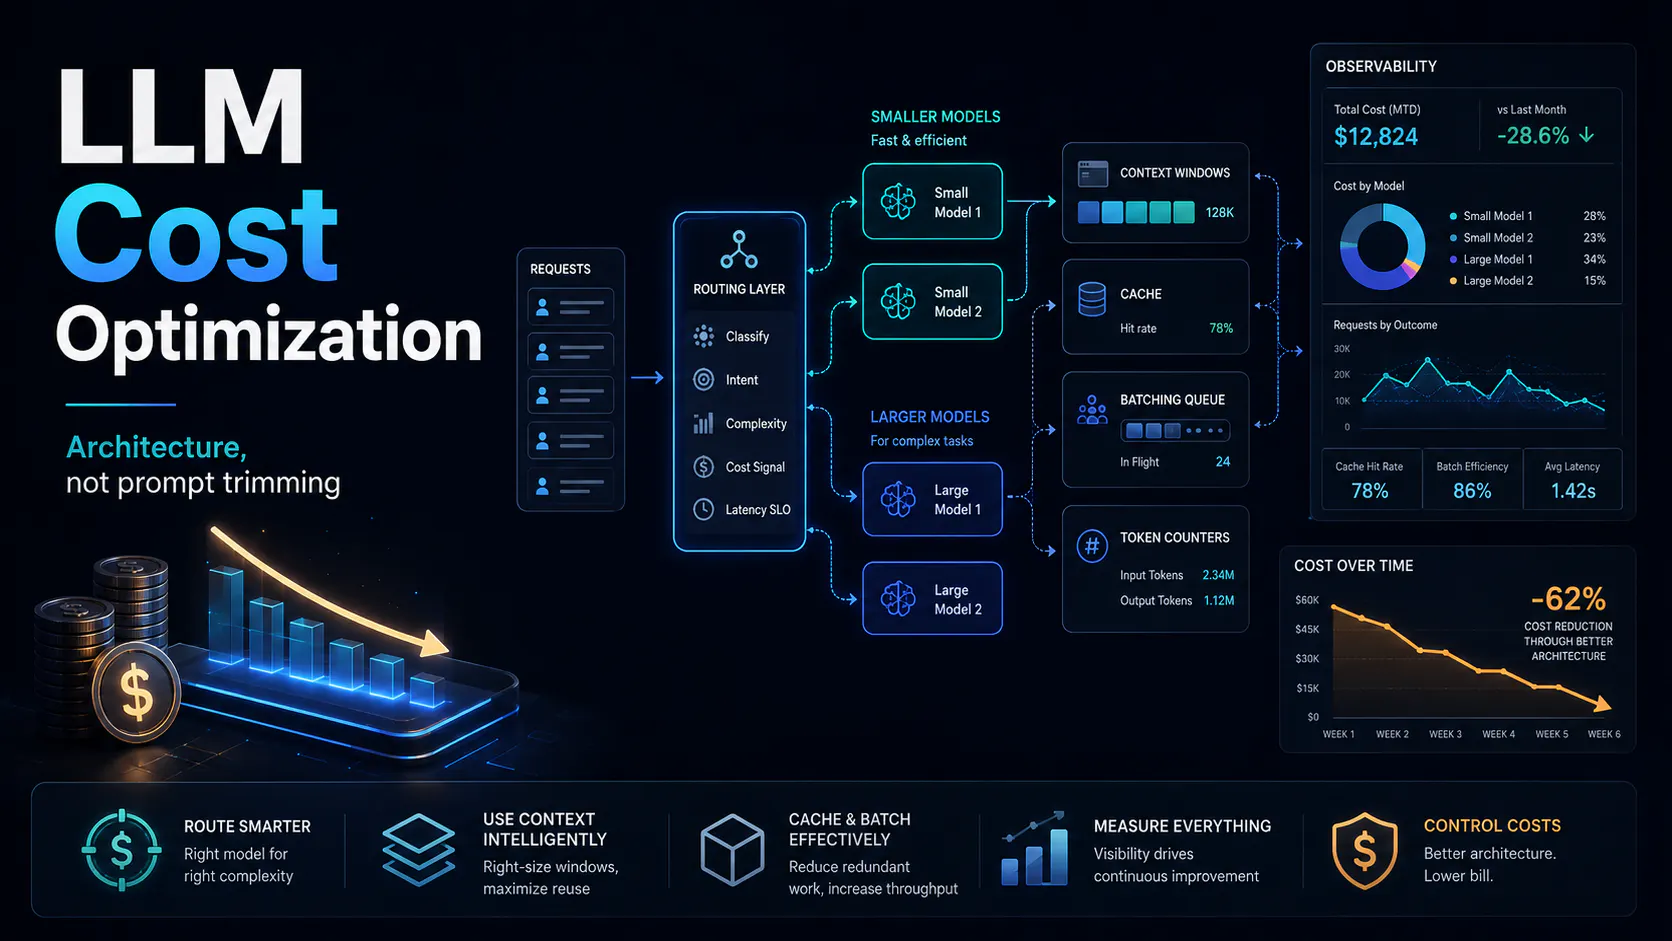
Reducing a 1,200-token prompt to 1,050 tokens is useful, but it does not fix an architecture that sends every request to the most expensive model, resends thousands of irrelevant context tokens on every turn, retries silently, generates text nobody displays, and processes overnight jobs through real-time endpoints.
LLM cost optimization is increasingly a systems problem.
The useful question is not:
How do we make this prompt cheaper?
It is:
Why did this request need...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE