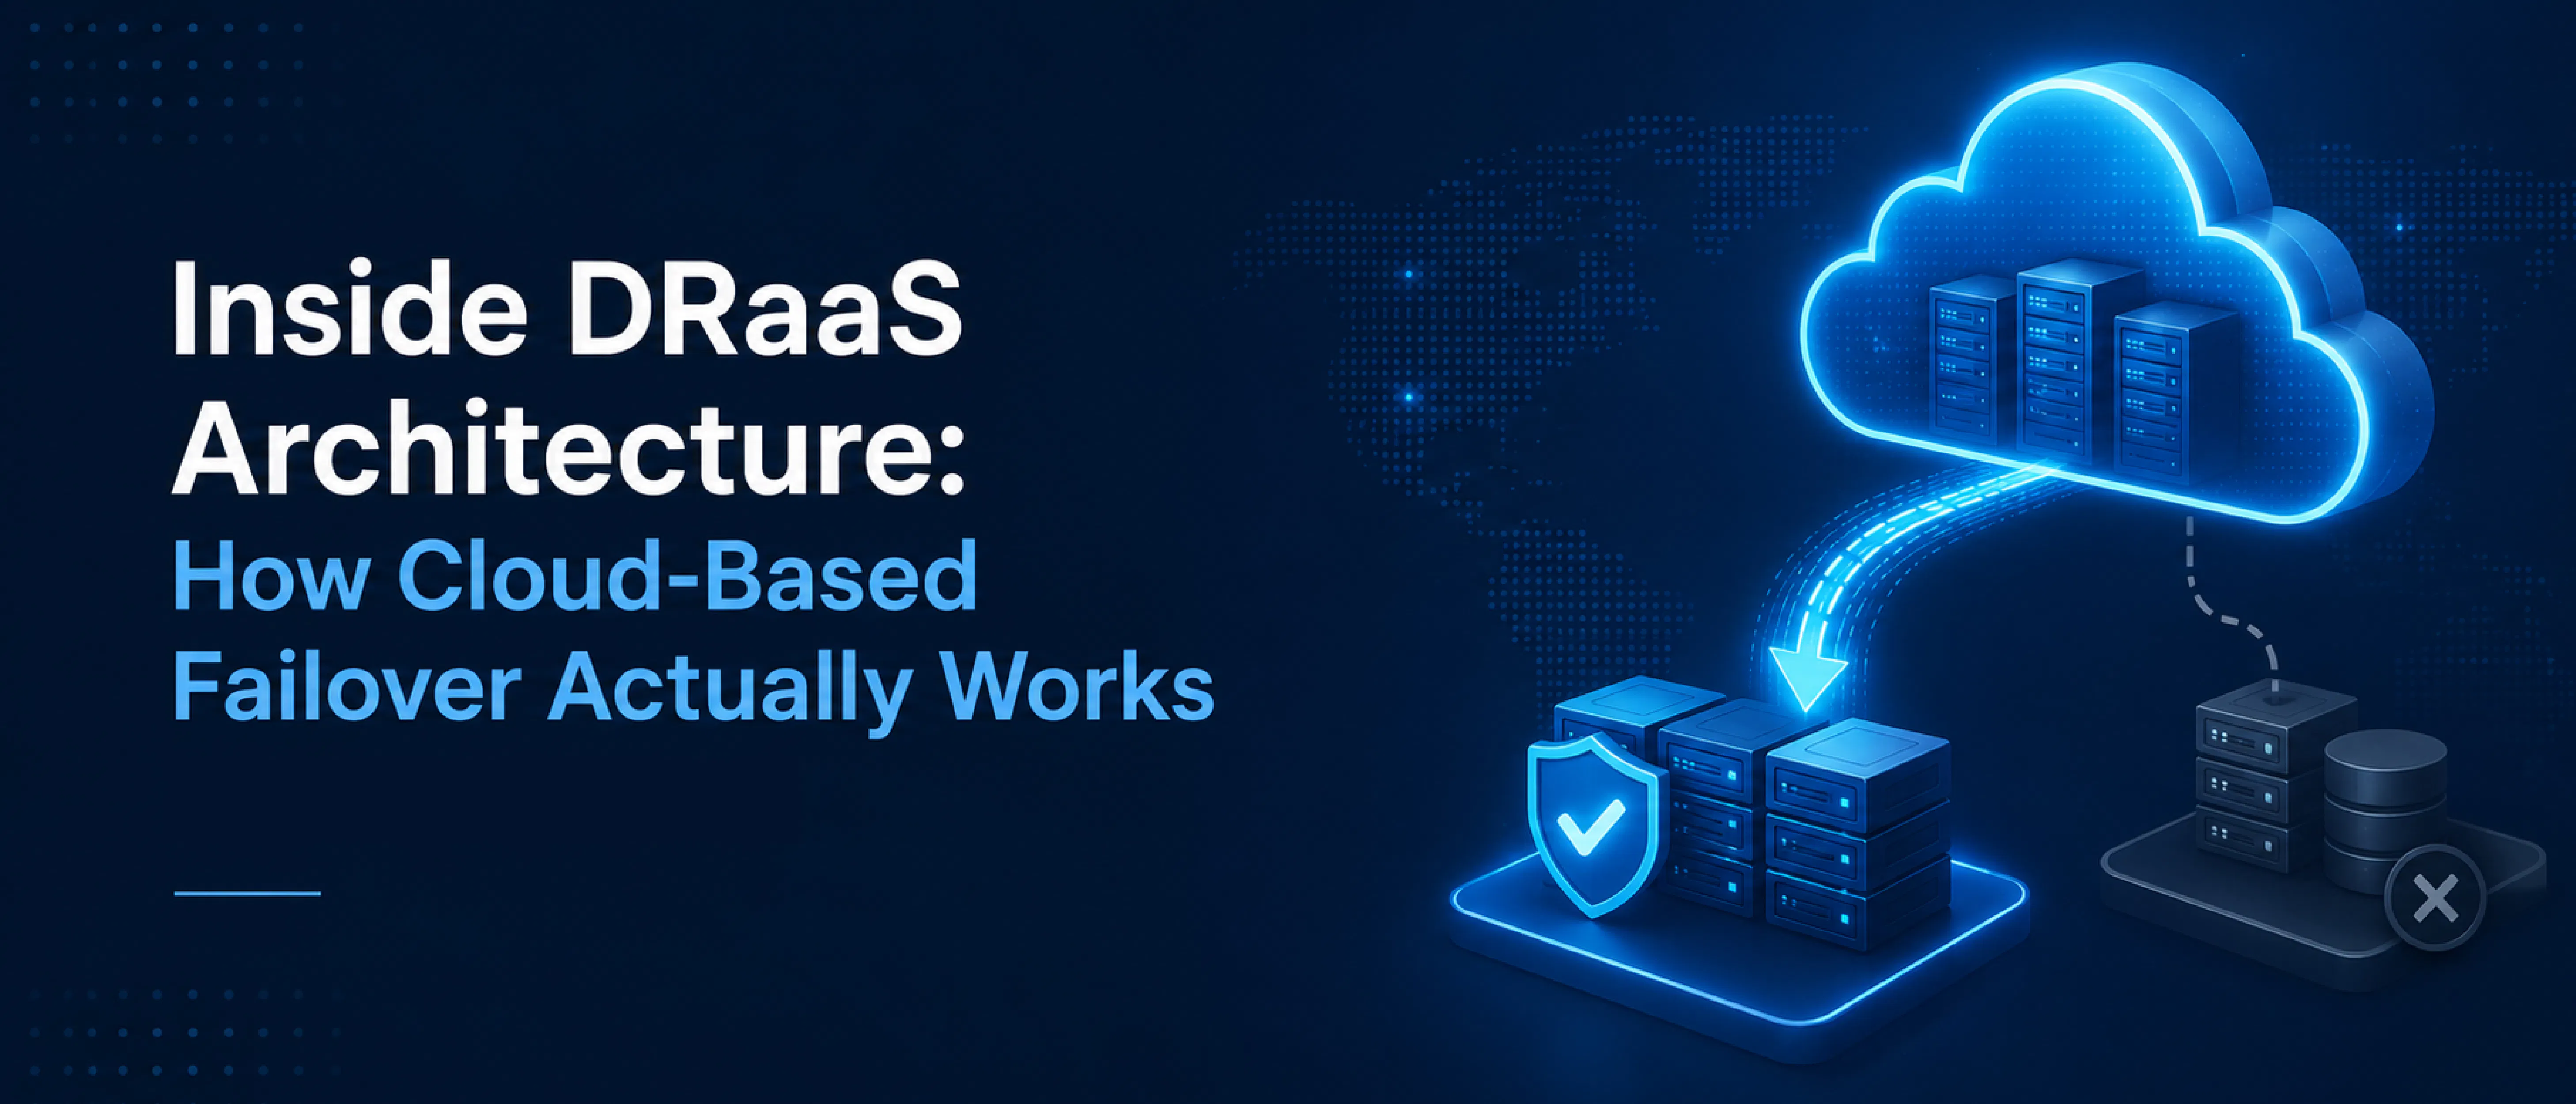
Inside DRaaS Architecture: How Cloud-Based Failover Actually Works (vs Traditional DR)
Most disaster recovery reviews sign off on the wrong thing. They confirm the servers came back, not whether anyone can actually use them. The database starts. The virtual machines report healthy. Monitoring turns green. The load balancer sees live endpoints and starts routing traffic. Someone tries to log in, and gets nothing.
Trace it back far enough and it's almost always the same story: the authentication service never failed over, still sitting at the primary site, still waiting for instructions nobody sent it. Sometimes it's a different dependency instead, but the shape of the failure never changes.
None of that trips a red flag on any dashboard. The infrastructure is up. The service isn't. Most DR diagrams don't even draw that distinction: production on one side, a recovery environment on the other, and an arrow between them that makes it look like the arrow is the hard part. It isn't....
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE