In RAG, Ten Sources Are Not Ten Pieces of Evidence
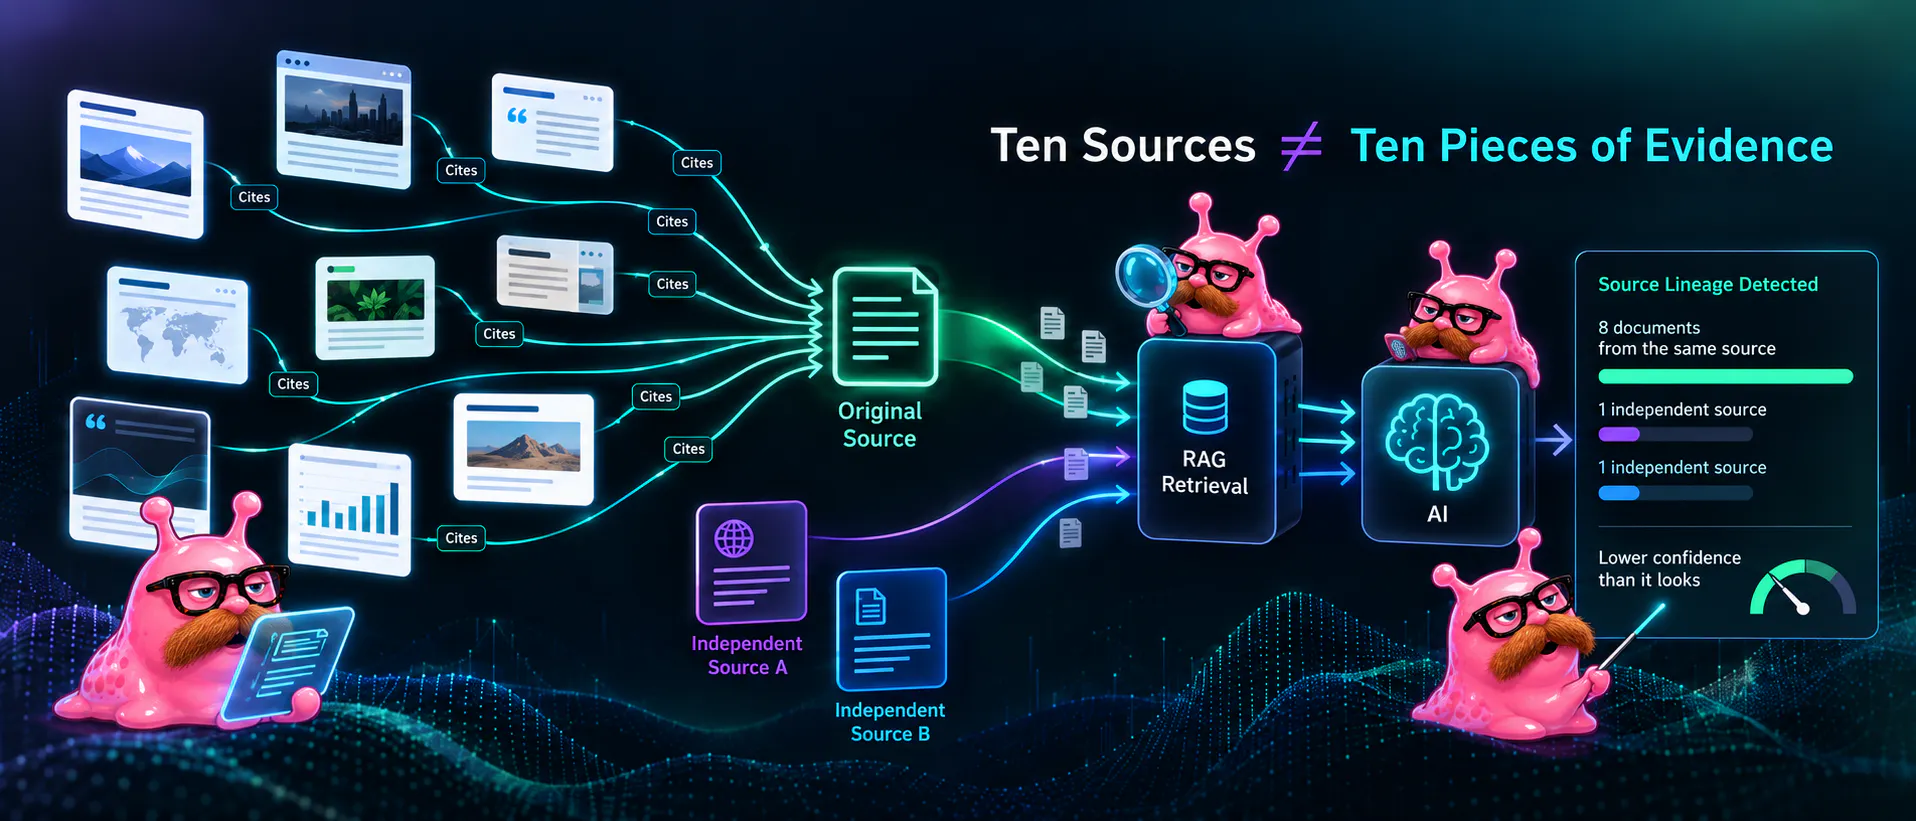
The Retrieval Count Is Not the Evidence Count
A typical retrieval pipeline has a simple mental model: find relevant chunks, rank them, pass the best ones to the model, and let agreement among them increase confidence. That works reasonably well when the retrieved sources are genuinely independent.
The internet is not independent.
News sites syndicate reporting. Blogs paraphrase documentation. Corporate announcements get rewritten by trade publications. Wikipedia pages cite articles that cite the same original document. Social posts repeat screenshots from a single account. Even technically different documents can belong to the same information chain.
Suppose a source A makes a claim. B, C, and D repeat A. Four other pages summarize B and C. A search engine retrieves all seven secondary pages plus A itself.
A naive system sees eight supporting documents. An influence-aware system sees something closer to one upstream lineage with multiple descendants.
Eight retrieved documents, but...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE