How We Caught an LLM Scoring Bug and Fixed It Without Compromising Our Research
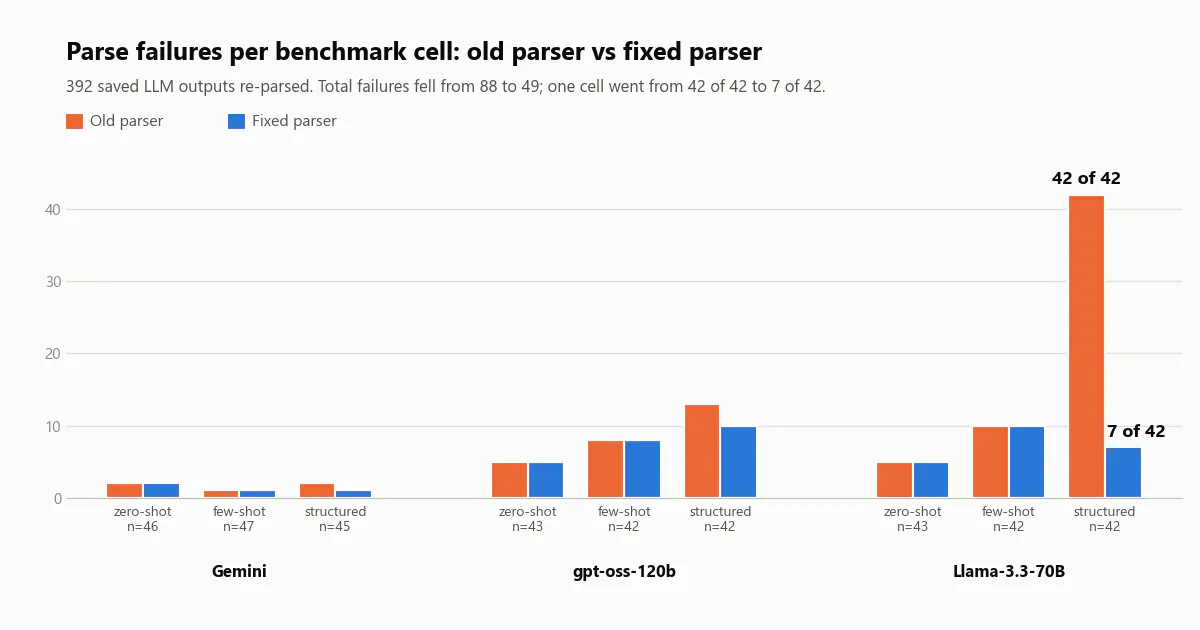
- One cell of our LLM benchmark showed a 100% failure rate (42 of 42 runs, recall 0.0). It looked like a model collapse. It was our parser.
- Of the 42 failures, 30 happened because the model did not repeat a field our code already knew. Only 5 were the JSON-formatting problem we expected.
- Fixing your scorer after you have seen the results is dangerous. We fixed only format problems, kept every content failure, never touched the raw outputs, and wrote tests that lock those rules in.
- A second, unrelated problem, hidden "reasoning" tokens eating the output budget on free-tier APIs, produced truncated answers that look like a model-quality difference. Both problems are easy to make and easy to miss.
What we were measuring
We built a benchmark to test whether large language models can write a project risk register from a project's planning documents. The ground truth is real: 21...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE