How to Find Vulnerable WordPress Sites Using Common Crawl
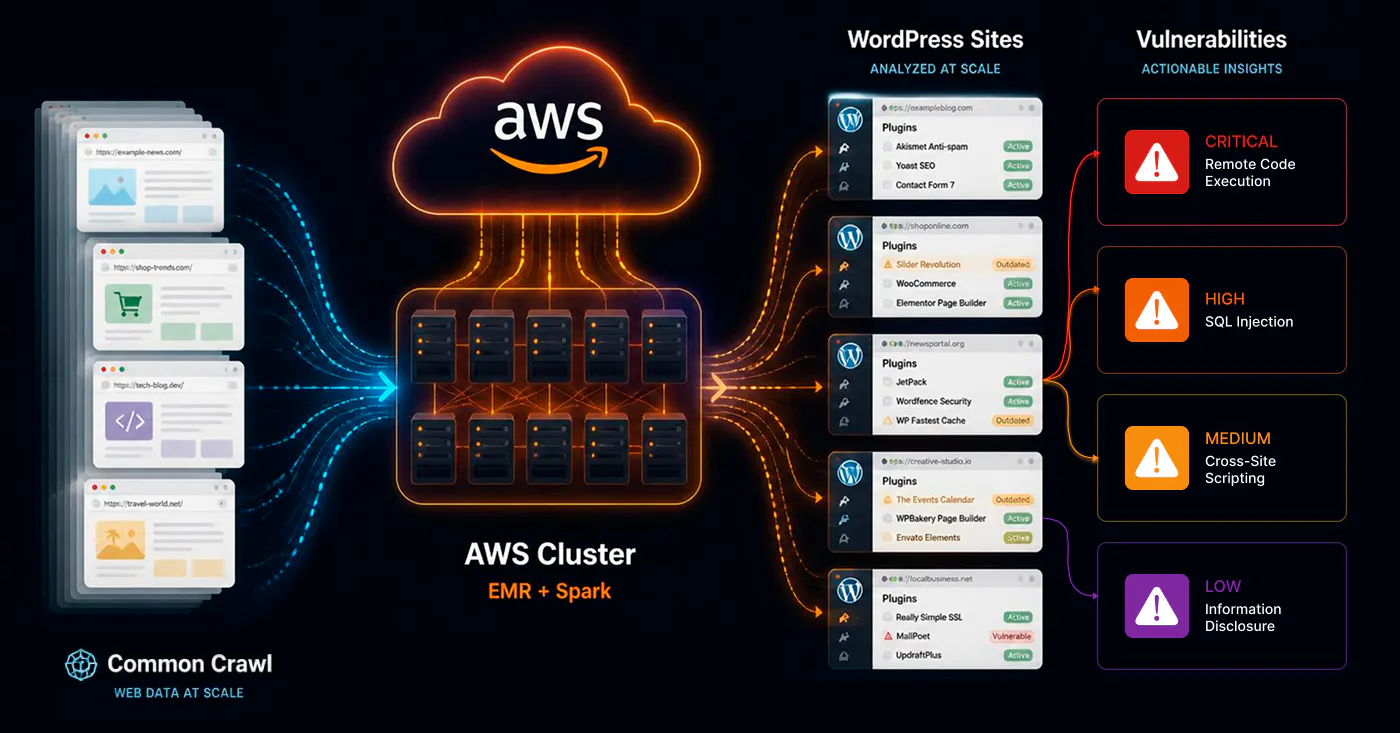
Recently, due to the rapid growth of WordPress websites, crawling the existing database of tens of millions of WordPress websites has become a challenge. And why bother when Big Data is available?
Everyone’s goals can be different, with good intentions, malicious ones, or even not-so-malicious ones. 😃 I’m an independent developer who loves to dig into different things and look for unconventional solutions to problems.
Common Crawl is a non-profit organization that collects website data into a massive archive of web pages, images, and metadata. The archive size for a single crawl is approximately 50 TB.
So, on one side of the scale, we have tens of millions of websites, and on the other, ~50 Tb of data.
You might say one is no better than the other—so what’s the benefit?
The Common Crawl archive is stored in Amazon S3 in theus-east-1region, and I’ll jump ahead and say...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE