How to Build Reliable LLM Classifiers With Confidence Thresholds
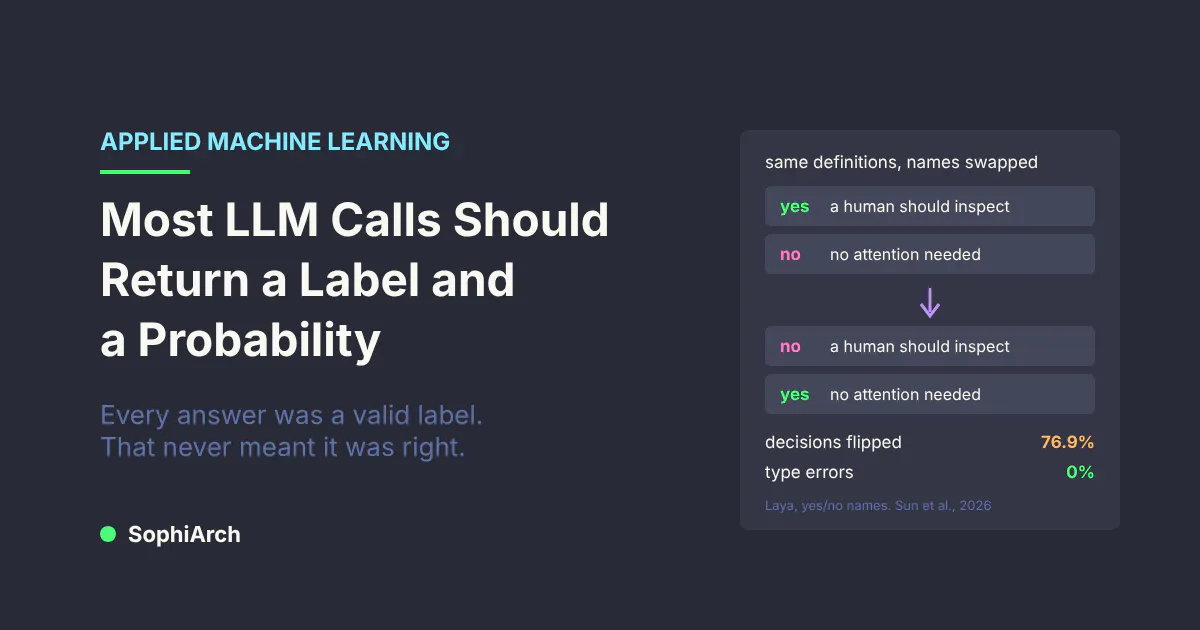
TL;DR: Routing, triage, moderation and approval prompts pick an answer from a list you wrote in advance. That makes them classifiers, but they usually skip what makes a classifier safe to run: label definitions the model actually follows, a labelled test set, a probability that means something, and a threshold with an escalation path. Schema-constrained output guarantees a validlabel, not a right one. In a September 2026 study, typed decision models were given the same definitions with the label names swapped between them. With yes/no names, one model changed 76.9% of its decisions, against 6.5% with 0/1 names, and its ranking went from 93.8% AUC to a below-chance 23.2%. The type-error rate was 0% the whole time. The same test runs on your own prompt in an afternoon and needs no labels. Then check whether the model's confidence ranks its own errors, set the threshold from what a mistake...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE