How Delta Lake Time Travel Saves Your Pipelines and ML Models
It’s 3:00 AM. A bad write from an automated pipeline just nuked critical user records, or your data science team realizes they can’t reproduce a breakthrough model because upstream source tables shifted yesterday. Sound familiar?
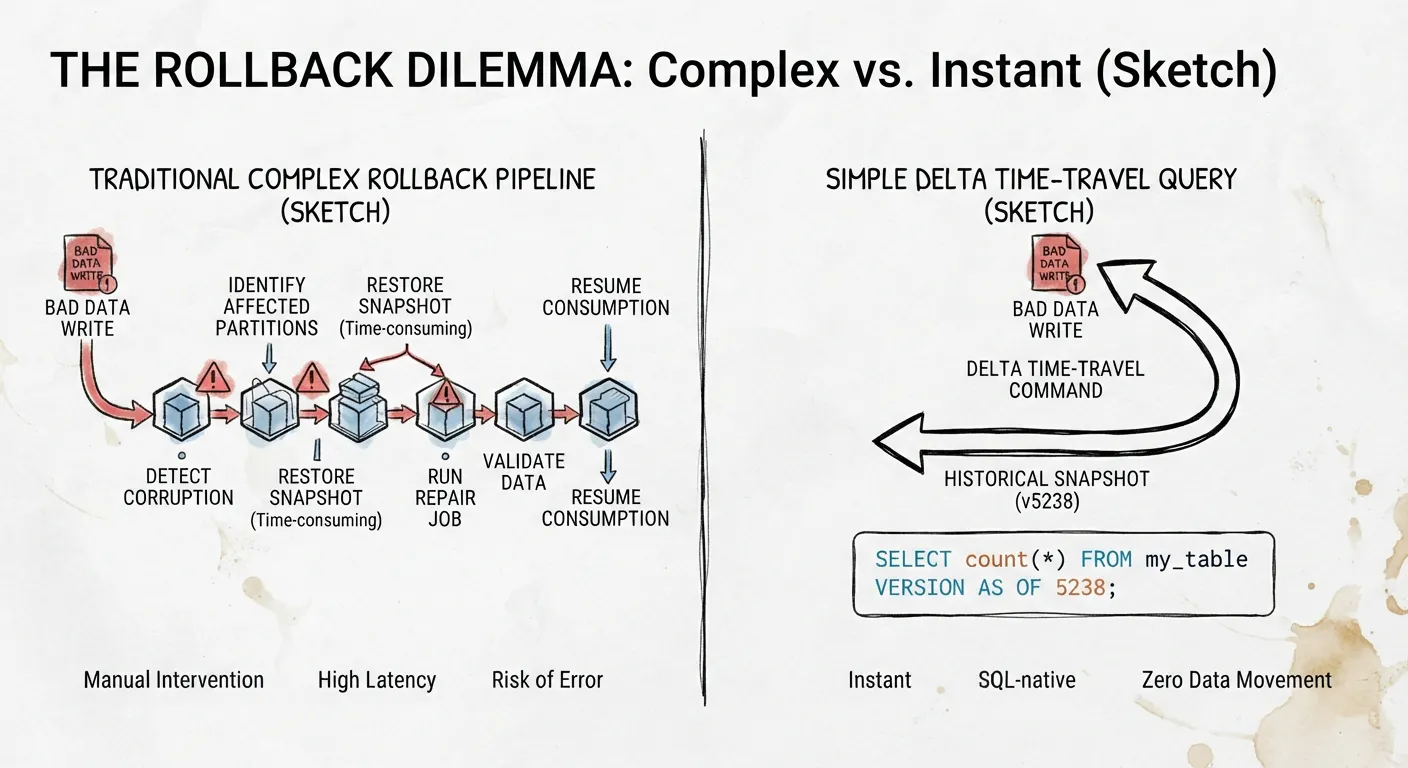
Managing large-scale data lakes often feels like walking a tightrope without a safety net. Data evolves, pipelines break, and historical state gets overwritten. But what if you could literally rewind time to see your data exactly as it looked last week, yesterday, or five minutes ago — without maintaining messy, expensive data duplicates?
Enter Delta Lake Time Travel. Built on top of Apache Spark, Delta automatically version-controls your big data lakehouse, giving data engineers, scientists, and analysts a powerful temporal safety net.
With Delta Lake Time Travel, you can effortlessly jump back to any historical version of your data lakehouse using a simple timestamp or version number — saying goodbye to complex backup pipelines...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE