Designing Default-Deny Egress Controls and Inline Policy Inspection for AI Agents
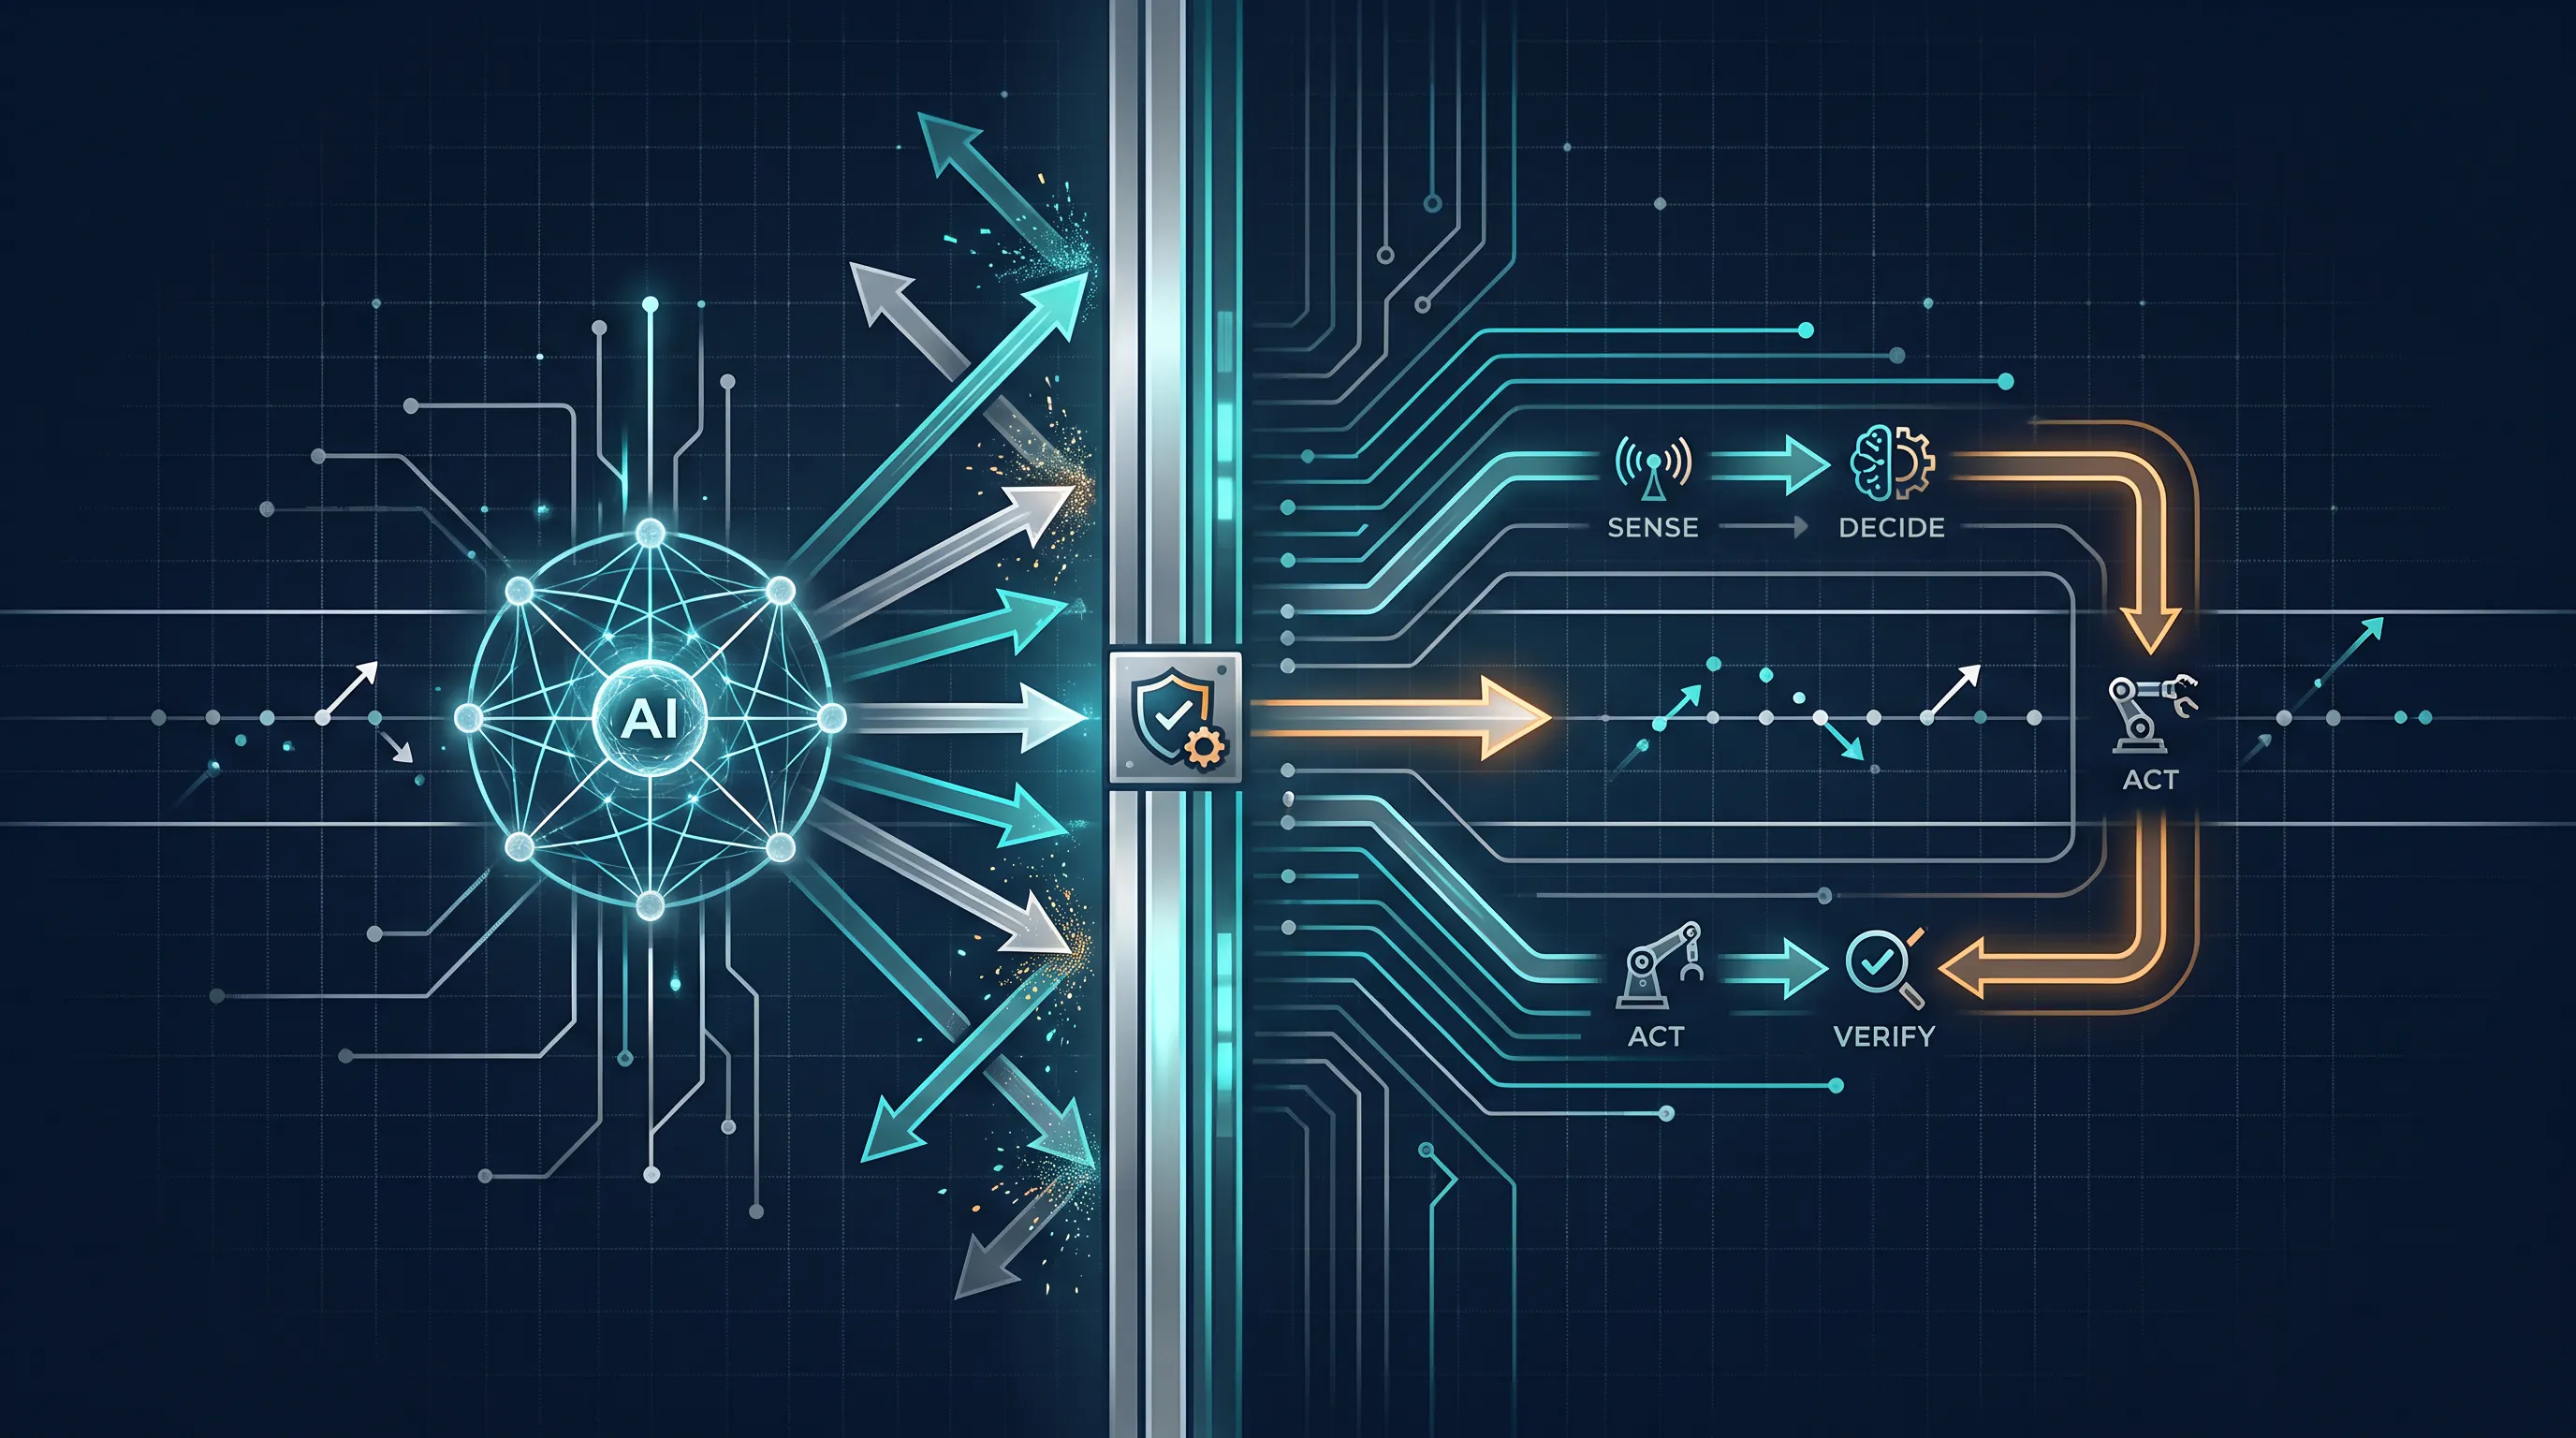
Most of the effort spent making AI agents "safe" goes into persuasion. Better system prompts. Sharper refusals. Longer lists of what the model must never do. We are, in effect, raising the agent to have good judgment and hoping it keeps that judgment under pressure.
Here's the discovery that flipped how I think about this: the two most active areas of AI security research in 2026, red-teaming and agent-behavior studies, are both quietly proving the same thing. Persuasion is not a boundary. Once I saw the pattern in both literatures at once, the whole "align it harder" approach started to look like a category error.
Start with red-teaming. Government safety institutes and frontier labs have stopped hand-crafting individual jailbreaks and started running automated, multi-turn, agent-versus-agent attacks at scale. The picture that comes back is genuinely two-sided, and the tension between the two halves is the interesting part.
On one side,...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE