

Building Named Entity Recognition for Code-Mixed Text with XLM-RoBERTa
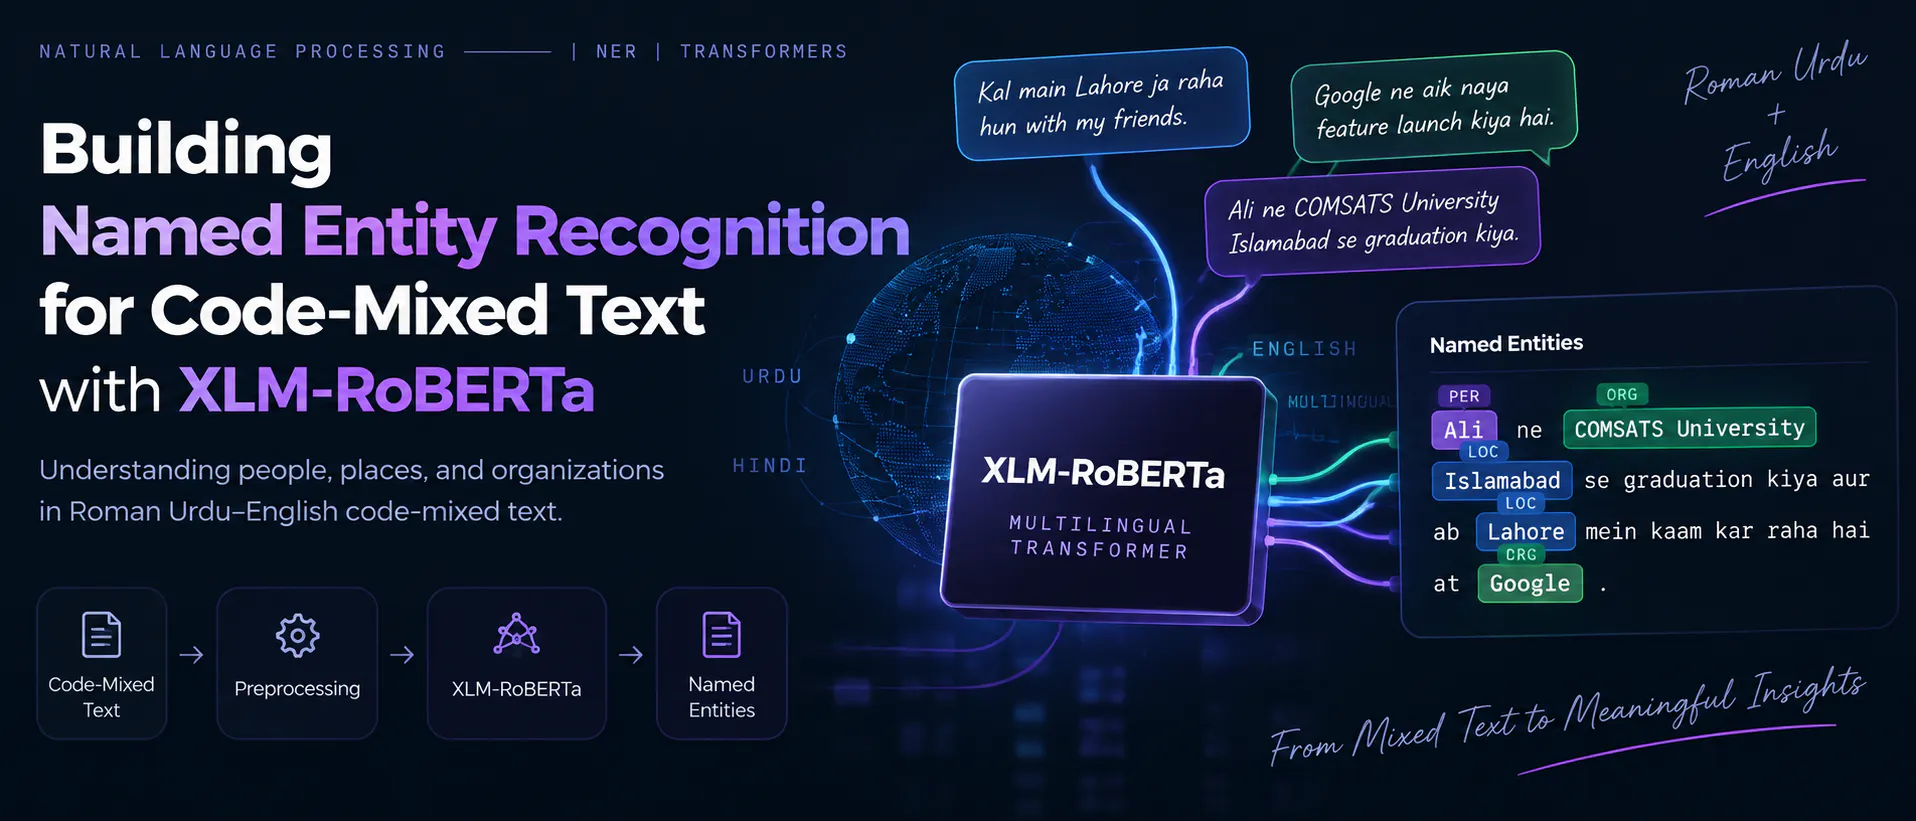
Named Entity Recognition (NER) is used to identify different types of entities in text, such as people, places, and organizations.
One of the most difficult parts of this project was the limited availability of rich datasets for Roman Urdu–English code-mixed text. Roman Urdu–English code-mixed text means that different languages, such as English and Roman Urdu, can be used within the same sentence.
This makes NER challenging because Roman Urdu can be written in many different ways. For example, one person may write a name as “Mehwish,” while another person may write it as “Mevish.” People can also spell Roman Urdu words differently according to their own writing style. Because of these spelling variations and the limited amount of available data, it is difficult for a model to learn all possible variations and make reliable predictions on different types of code-mixed text.
The Problem with Code-Mixed NER
The main challenge in...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE


