Building Enterprise Context Pipelines: Retrieval, Orchestration, and Cloud-Native Architecture
From Principles to Pipelines
In Part 1, we made the case that an AI system is only as effective as the information it receives, and we described what makes context reliable: relevance, freshness, completeness, trustworthiness, and authorization. Those five dimensions are useful as a checklist, but they raise an obvious follow-up question. How do you actually produce context that meets them, for every request, at enterprise scale?
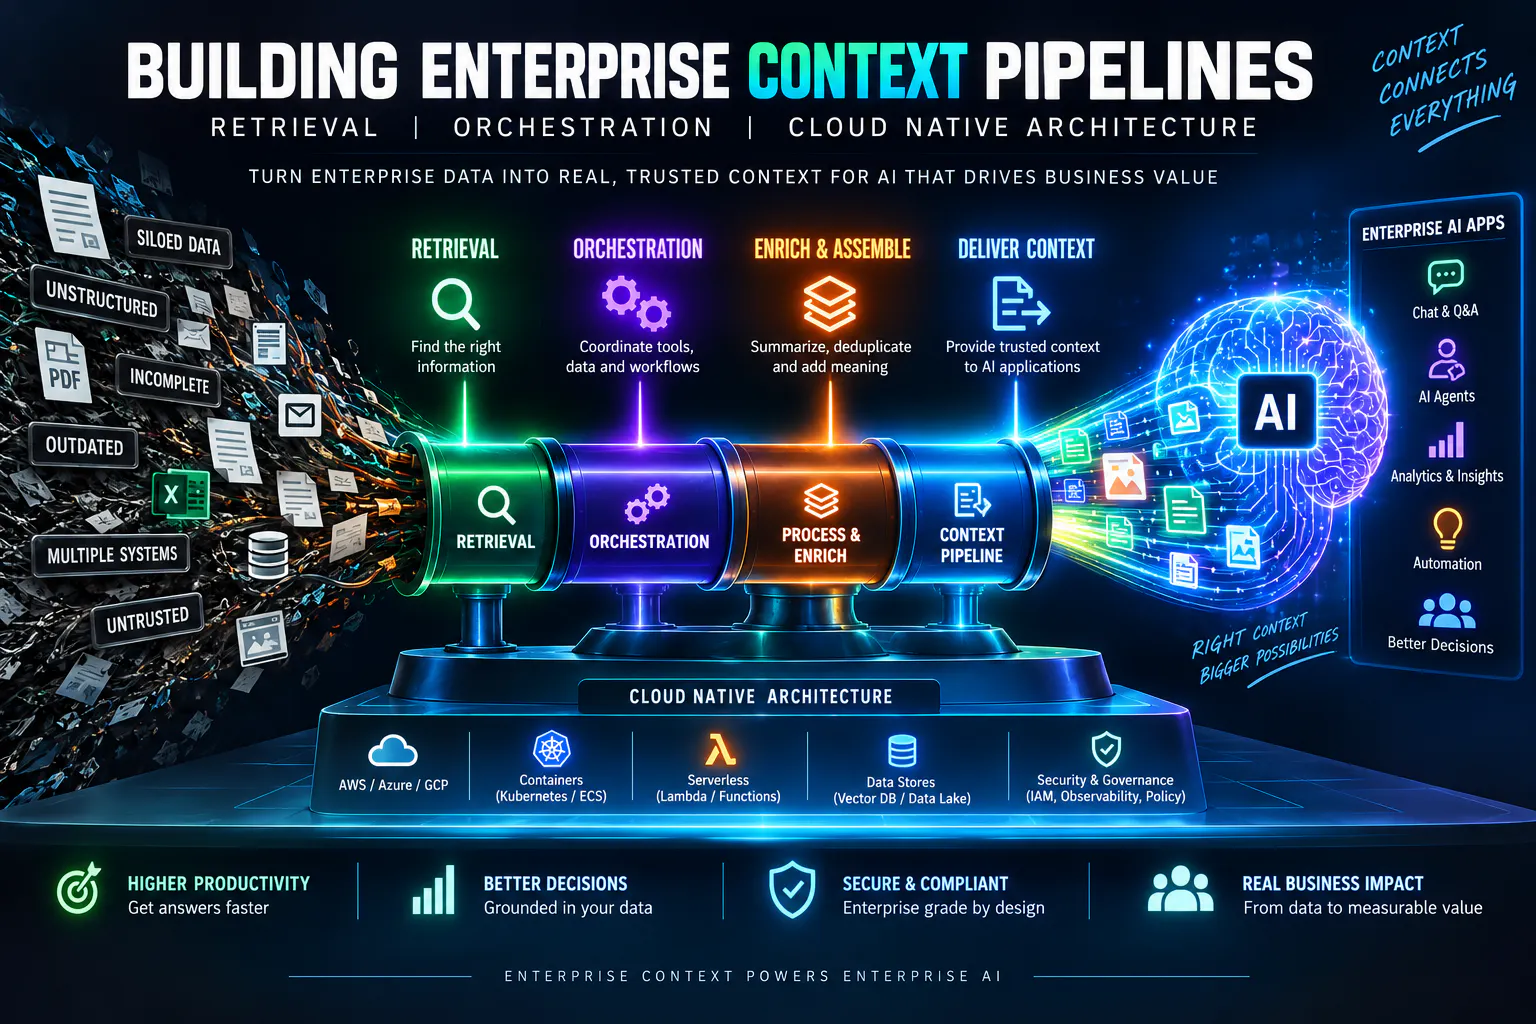
That is the work of a context pipeline. A prompt is a single instruction. A context pipeline is the system that decides what information reaches the model, in what form, and under what controls, every time a user or application asks a question. This article walks through how that pipeline is built, from the raw data sources all the way to the assembled prompt, and shows how cloud-native services make each stage practical.
Key Takeaways
- Enterprise context comes from many sources, and...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE