Benchmarking Claude Haiku, Sonnet, and Opus on 64 Broken Data Pipelines
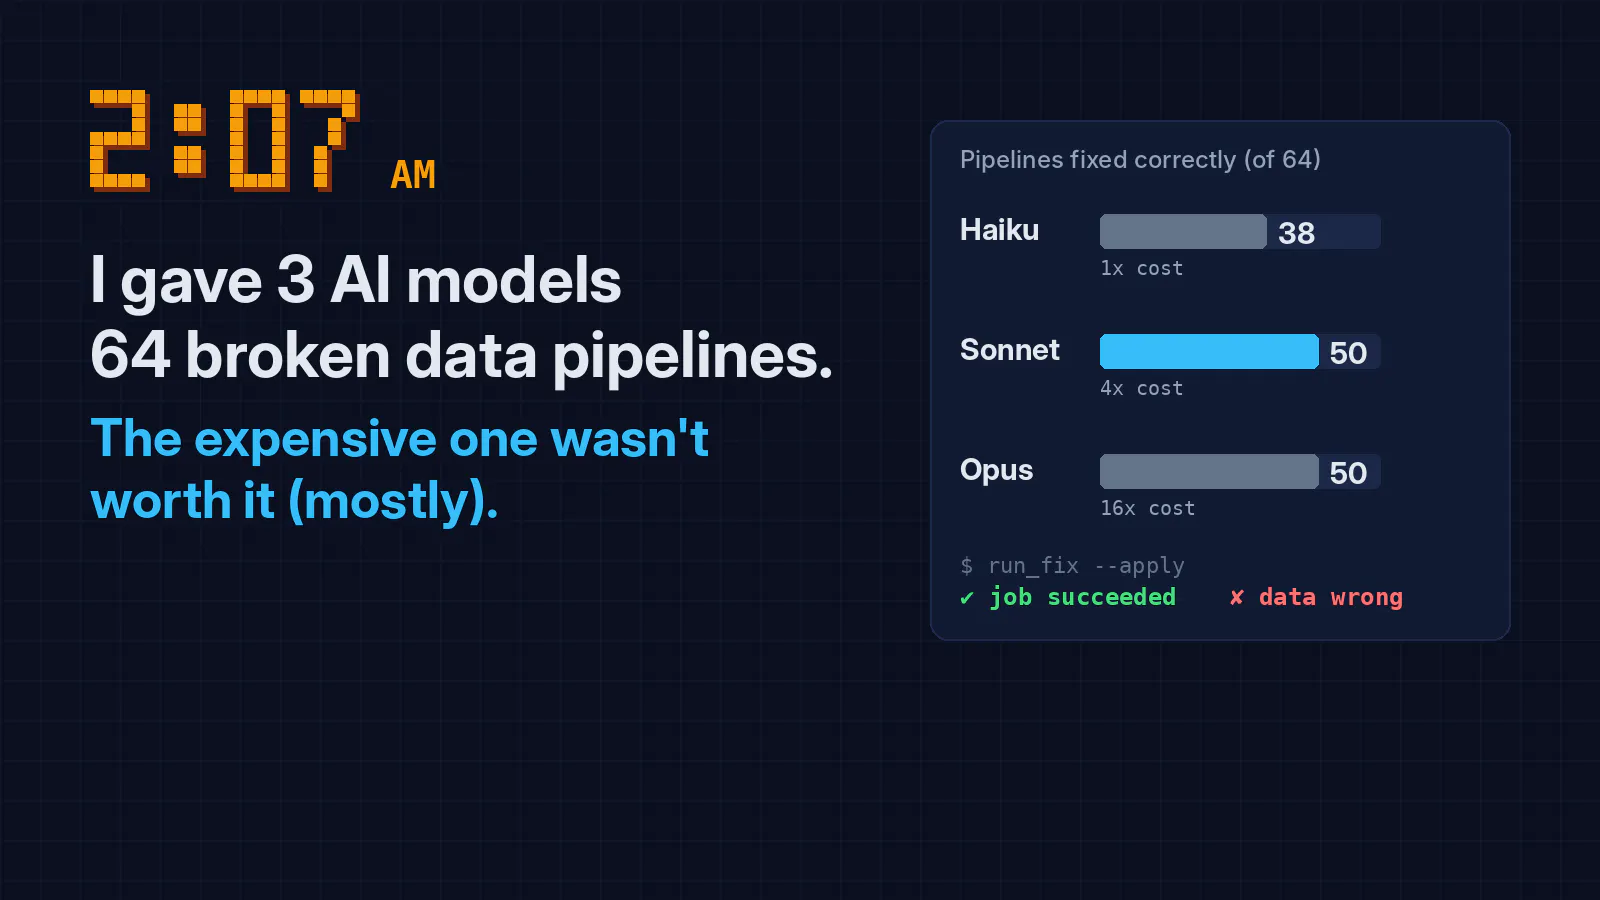
2:07 a.m.
The phone buzzes. The nightly transactions job has failed again. You open the laptop, squint at the error, find the batch that came in twice, write a quick dedupe, rerun, watch it go green, and crawl back to bed.
Three days later finance asks why one region’s revenue is off.
If you’ve been in data engineering long enough, you’ve lived some version of that night. I’ve lived it for 15 years. So when teams started asking me whether they could hand that 2 a.m. page to an AI agent, I didn’t have a confident answer. And the question they always asked next was even harder: which model?
The small one is cheap and fast. The big one is supposedly smarter. Nobody wants to pay for the big one if the small one would do. I wanted a real answer, not a vibe. So I built a test and...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE