Another View on Context Parallel for LLMs: Balancing Compute
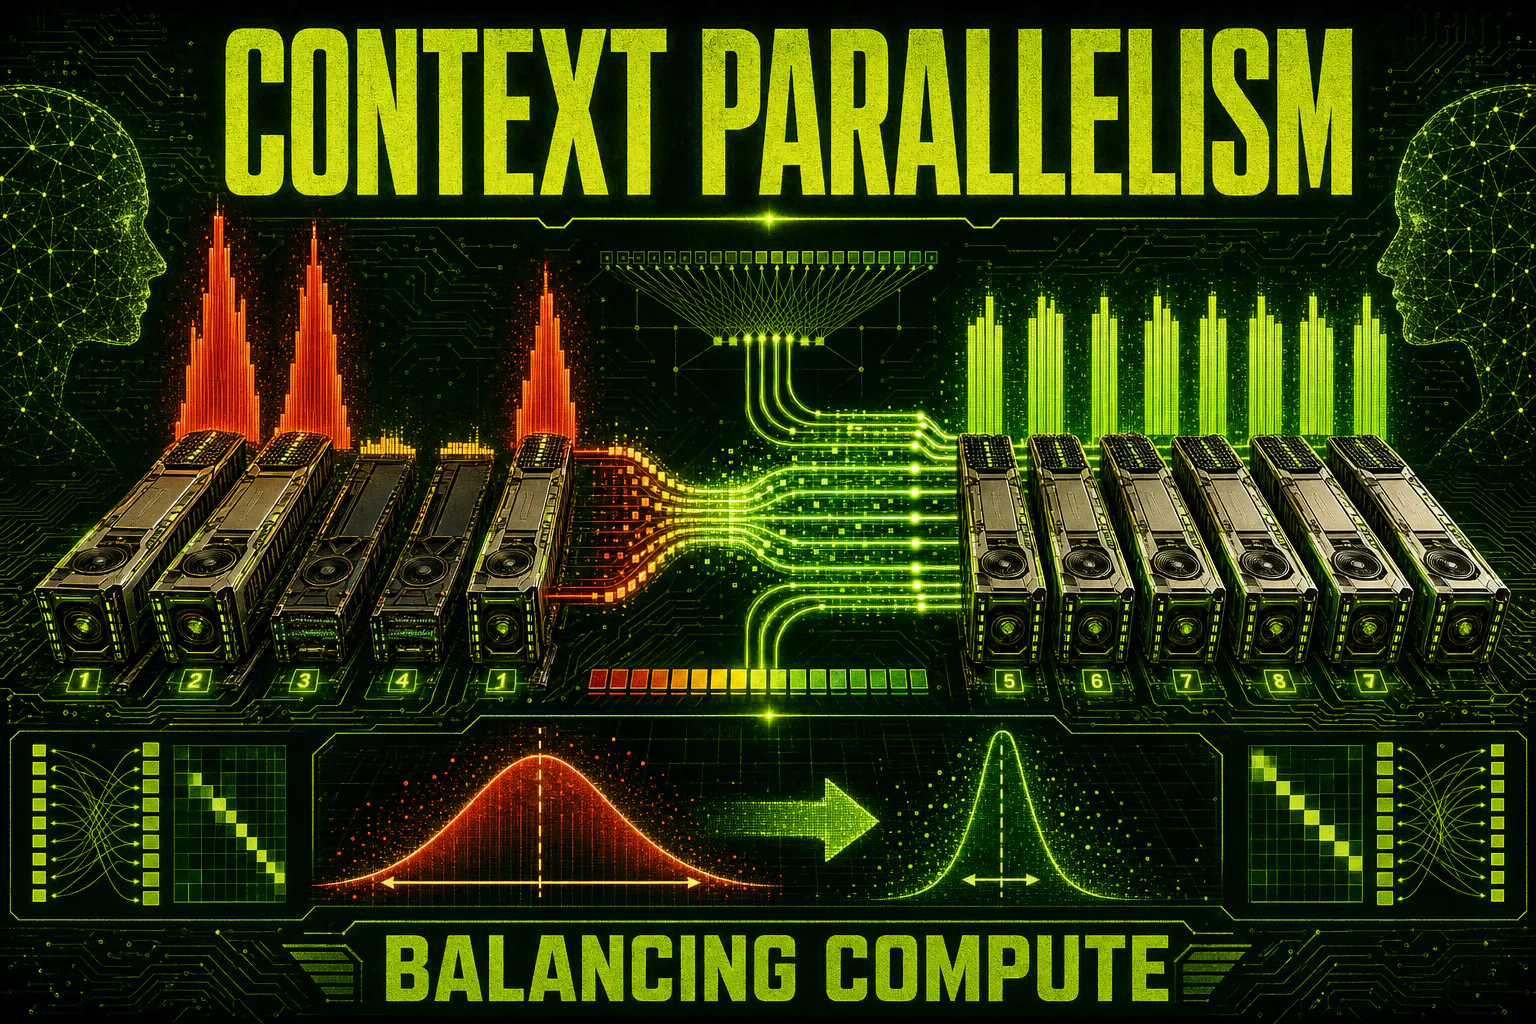
Context Parallelism (CP) splits a batch along the sequence-length dimension, allowing each CP rank to process only a chunk of the original sequence and reducing the memory required for training. I use CP to mean any technique that splits the context length and processes it independently, without relying on Tensor Parallelism, to clearly distinguish Sequence Parallelism from Context Parallelism.
Two of my favorite resources motivate CP in terms of long sequences.
Self-Attention, which is the key component of Transformers, suffers from quadratic memory requirements with respect to the sequence length, therefore when sequence length gets to a certain length, even a batch size of 1 might not be able to fit onto a single GPU and require additional partitioning along the sequence dimension. And once this is done, the sequence can be of any length.
Context Parallelism (CP) specifically targets the challenge of training with very...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE