A Negative KL Penalty Doesn't Mean Your AI Agent's Reward Calculation Is Broken
A code agent generates a response. You compare its token log probabilities with those from a fixed reference policy, calculate a penalty, and discover that the “KL term” is negative.
The tempting fix is one line:
penalty = max(0, penalty)
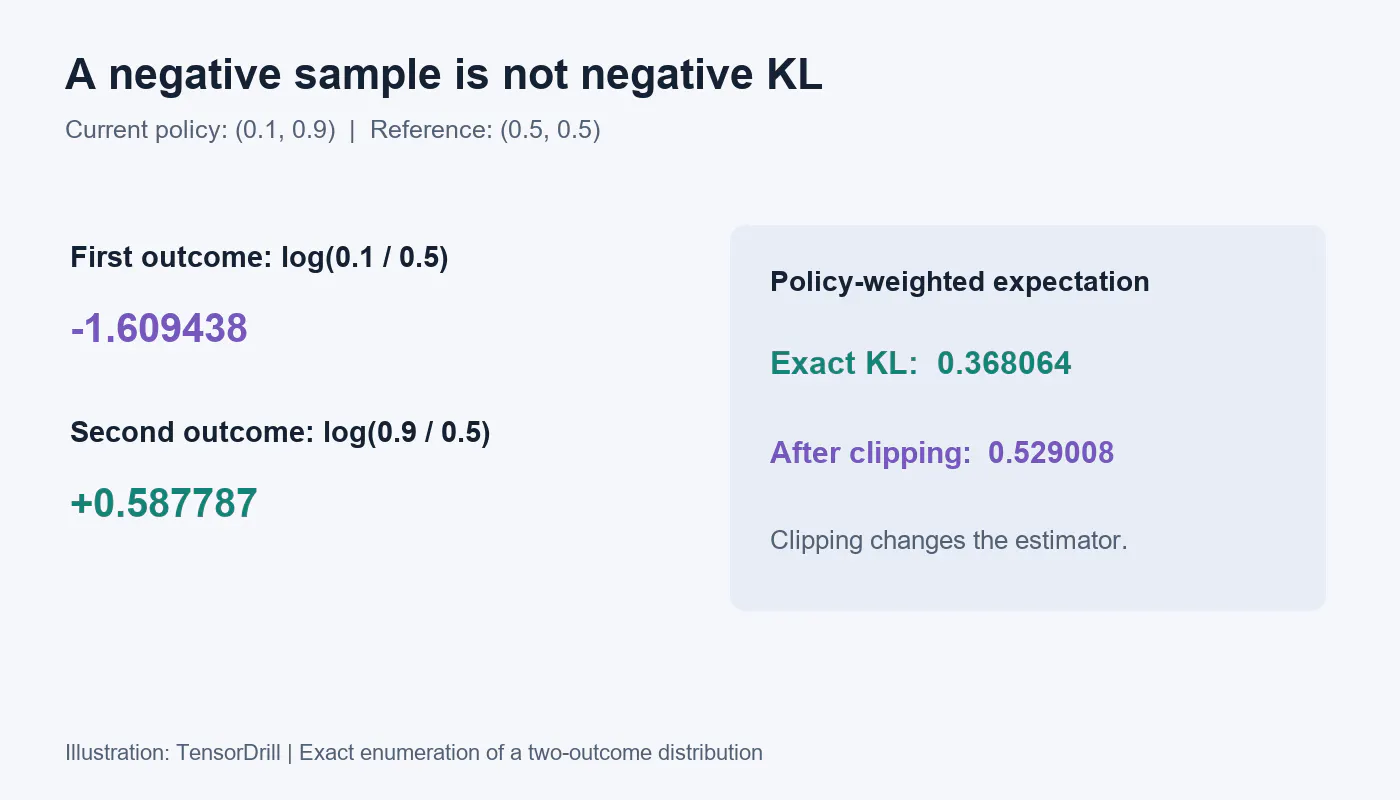
Before adding it, check what the number actually represents. An individual sampled log probability ratio can be negative even though the exact KL divergence between normalized distributions is nonnegative. Clamping the former changes the quantity you are estimating.
This distinction is easy to miss when implementing reward bookkeeping for execution-feedback code agents. We can examine it using Python's standard library and a two-outcome distribution.
Start with a distribution small enough to enumerate
Let the current policy assign probabilities (0.1, 0.9) to two possible outcomes. Let the reference assign (0.5, 0.5).
For a sampled outcome, calculate log(policy_probability / reference_probability):
Current policy
Sampled log ratio
The first outcome is less likely under...
Copyright of this story solely belongs to hackernoon.com. To see the full text click HERE